- Published on
Driving Multilogin browser profiles with Puppeteer and a LangGraph agent
- Authors

- Name
- Nadim Tuhin
- @nadimtuhin
On this page
Disclaimer: This is an educational deep-dive into browser automation architecture. The techniques shown can be used for legitimate purposes like testing, research, and managing your own accounts. Don't be evil: respect ToS and rate limits.
I hate maintaining Puppeteer scripts.
Every time a website updates its UI, my selectors break. Every time it adds a new modal, my automation fails. I was spending more time fixing scripts than using them.
So I built something different: browser agents that think.
Instead of hardcoding document.querySelector('.xyz123'), the AI works out what to click from what it sees. The site renamed its button from "Submit" to "Post"? The agent adapts. A new confirmation dialog? It handles it.
Here's the stack:
- Multilogin: Run 50+ browser profiles without getting fingerprinted
- Puppeteer: The muscle for clicking, typing, and navigating
- LangChain ReAct: The reasoning loop that decides what to click
What it looks like in action
No hardcoded CSS selectors. The agent reads the DOM tree and decides:
Agent: "Task: Fill out the contact form and submit"
Agent: "Looking for input fields... found Name, Email, Message"
Agent: "Typing into the Name field..."
Agent: "Typing into the Email field..."
Agent: "Looking for the submit button... found 'Send Message'"
Agent: "Clicking submit..."
Agent: "Checking for confirmation... found 'Thank you!' message"
Agent: "Success! Form submitted."
Here's the point: I didn't write a single selector. The AI figured it out.
Traditional automation vs autonomous agents
| Traditional automation | AI-powered automation |
|---|---|
#submit-btn-v3 breaks when they rename it | "Click the submit button" always works |
| Fails silently on UI changes | Adapts or explains why it's stuck |
| One script per website | Same agent, any website |
| Hours debugging selectors | Minutes tweaking prompts |
Traditional automation flow:
- Website updates -> Button renamed (
#submit-v3->#post-btn) - Script fails -> "Element not found"
- Developer spends weekend fixing selectors
AI-powered automation flow:
- Website updates -> Button renamed (
#submit-v3->#post-btn) - AI finds button by text/ARIA attributes
- Adapts to new DOM structure automatically
Architecture
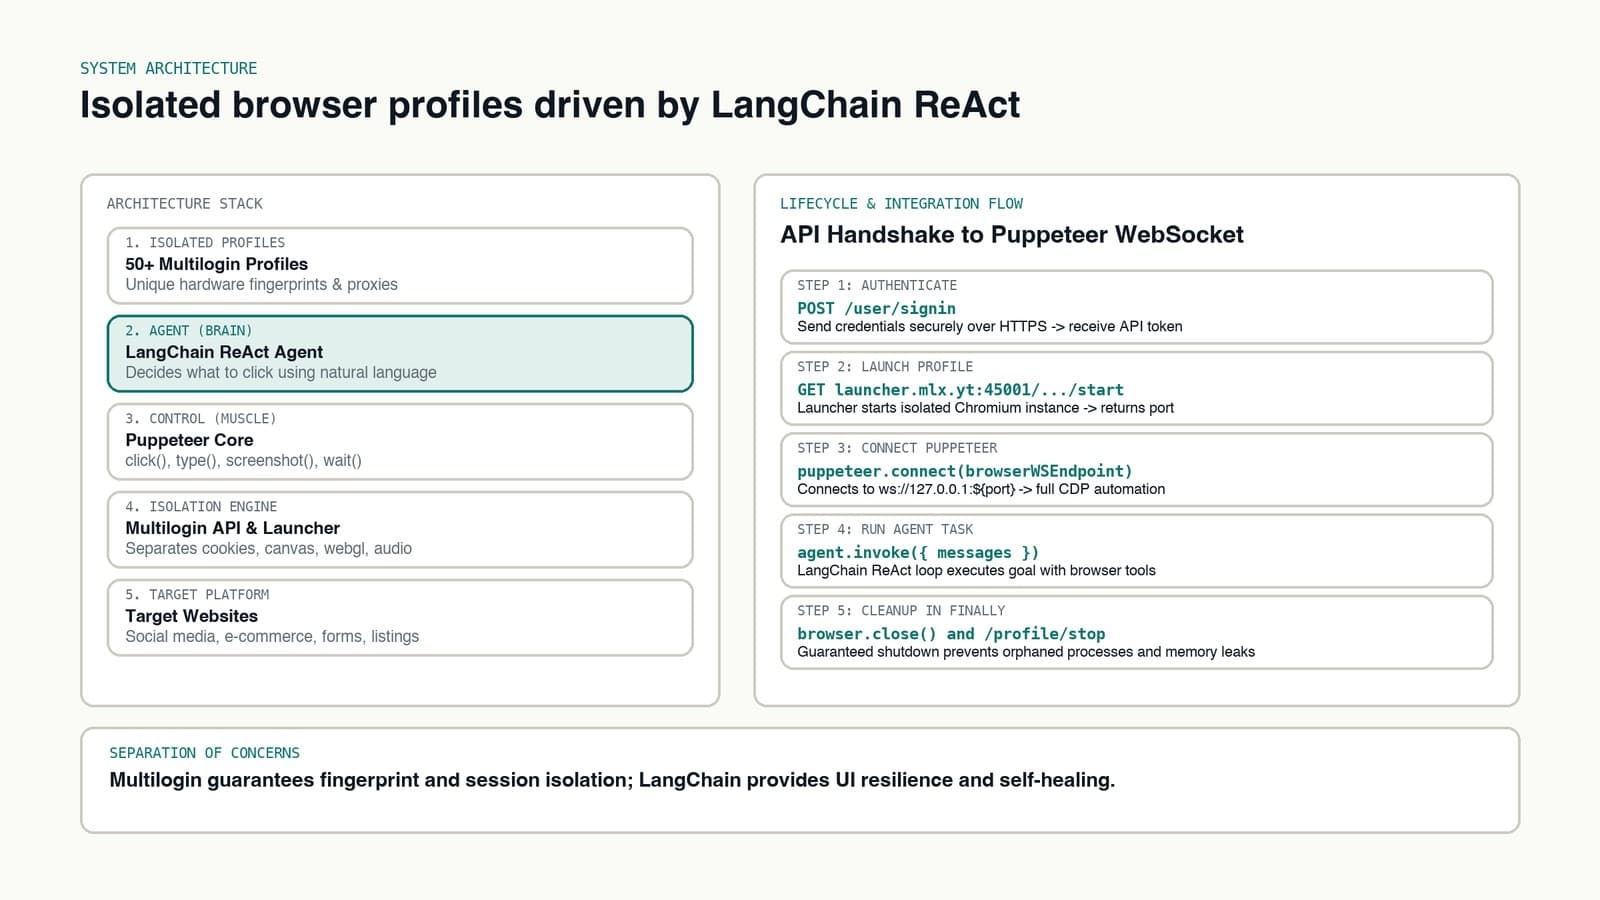
| Layer | Component | Purpose |
|---|---|---|
| Profiles | Profile 1, 2, ... N | Isolated accounts (A, B, X) |
| Agent | LangChain ReAct | Think -> Act -> Observe -> Repeat |
| Control | Puppeteer | click(), type(), screenshot(), wait() |
| Isolation | Multilogin | Unique fingerprint, cookies, proxy, session |
| Target | Website | The site being automated |
Why Multilogin? Each profile gets its own browser fingerprint, cookies and session. You can run 50 profiles at once without them looking like they come from the same machine.
The control plane runs the task queues and manages profile lifecycles. Worker agents do the tasks, each in its own isolated browser:
+-----------------------------------------------------------------------+
|                            CONTROL PLANE                              |
|                                                                       |
|  +--------------------+   REST API    +----------------------------+  |
|  | Task Orchestrator  | ------------> | Multilogin Local Launcher  |  |
|  | (Node.js / p-limit)|               | (127.0.0.1:45001)          |  |
|  +--------------------+               +----------------------------+  |
|            |                                        |                 |
|            | dispatches tasks                       | boots profiles  |
|            v                                        v                 |
+-----------------------------------------------------------------------+
|                                                                       |
|                       BROWSER AGENT INSTANCES                         |
|                                                                       |
|  +-------------------------------+   +-----------------------------+  |
|  | Agent Instance 1              |   | Agent Instance 2            |  |
|  |                               |   |                             |  |
|  | +---------------------------+ |   | +-------------------------+ |  |
|  | | LangChain ReAct Loop      | |   | | LangChain ReAct Loop    | |  |
|  | | (Reasoning + LLM calls)   | |   | | (Reasoning + LLM calls) | |  |
|  | +---------------------------+ |   | +-------------------------+ |  |
|  |               |               |   |              |              |  |
|  |               v               |   |              v              |  |
|  | +---------------------------+ |   | +-------------------------+ |  |
|  | | Puppeteer Core Client     | |   | | Puppeteer Core Client   | |  |
|  | +---------------------------+ |   | +-------------------------+ |  |
|  |               | ws://port_A   |   |              | ws://port_B  |  |
|  |               v               |   |              v              |  |
|  | +---------------------------+ |   | +-------------------------+ |  |
|  | | Isolated Profile (A)      | |   | | Isolated Profile (B)    | |  |
|  | | - Canvas noise injected   | |   | | - Canvas noise injected | |  |
|  | | - Synced cookies/storage  | |   | | - Synced cookies/storage| |  |
|  | | - Dedicated proxy tunnel  | |   | | - Dedicated proxy tunnel| |  |
|  | +---------------------------+ |   | +-------------------------+ |  |
|  +-------------------------------+   +-----------------------------+  |
+-----------------------------------------------------------------------+
                   |                                   |
                   v                                   v
          [ Target Website A ]                [ Target Website B ]
Prerequisites and environment setup
Install the packages:
npm install puppeteer-core axios
npm install @langchain/core @langchain/langgraph @langchain/openai
Note: Multilogin uses HTTP API authentication, not a dedicated npm SDK. The examples below talk to its API directly.
Then the environment variables:
# Multilogin credentials
MULTILOGIN_EMAIL=your-email@example.com
MULTILOGIN_PASSWORD=your-password

# LLM provider (choose one)
OPENAI_API_KEY=sk-...
GEMINI_API_KEY=AIz...
ZAI_API_KEY=...

# Optional: Specific model
AI_MODEL=gpt-4o-mini
Signing in to the control plane
Multilogin treats each browser profile as its own container. A profile carries its own local storage, IndexedDB, cookie store and virtual hardware fingerprint. Your automation code manages these containers through a central control plane.
First you sign in to the cloud API to get a session token. That token authorizes calls to the local launcher daemon, which runs the browser processes on your machine.
import axios from 'axios'

// Multilogin API client helper
// Note: Multilogin uses standard HTTPS - passwords are sent securely over TLS
async function getMultiloginToken(email: string, password: string): Promise<string> {
  const response = await axios.post('https://api.multilogin.com/user/signin', {
    email,
    password, // Sent securely over HTTPS
  })
  return response.data.data.token
}

// Create authenticated client
const token = await getMultiloginToken(
  process.env.MULTILOGIN_EMAIL!,
  process.env.MULTILOGIN_PASSWORD!
)
Security note: Always use environment variables for credentials. Never commit passwords to source control.
Starting a profile and connecting Puppeteer
Starting a profile kicks off a local sync. The launcher daemon pulls the profile config, warms the local cache, applies proxy settings and boots the browser engine. Multilogin uses its own browser engines (Mimic for Chromium, Stealthfox for Firefox), which inject hardware fingerprints at the C++ layer.
Once the profile is up, the launcher exposes a local Chrome DevTools Protocol (CDP) WebSocket port. Puppeteer connects straight to it with puppeteer.connect().
The browser engine manages storage natively, so session cookies, local storage and auth tokens survive process restarts. When the session ends, the launcher syncs the changes back to the profile store.
import puppeteer from 'puppeteer-core'

// Launch profile via Multilogin API
async function startProfile(
  token: string,
  folderId: string,
  profileId: string,
  headless = false
): Promise<{ port: number }> {
  const url = `https://launcher.mlx.yt:45001/api/v2/profile/f/${folderId}/p/${profileId}/start?automation_type=puppeteer&headless_mode=${headless}`

  const response = await axios.get(url, {
    headers: { Authorization: `Bearer ${token}` },
  })

  return response.data.data
}

// Launch and connect
const { port } = await startProfile(token, 'your-folder-uuid', 'your-profile-uuid')

// Connect Puppeteer to Multilogin profile
const browser = await puppeteer.connect({
  browserWSEndpoint: `ws://127.0.0.1:${port}`,
})

const page = await browser.newPage()
await page.setViewport({ width: 1920, height: 1080 })

console.log('Browser started on port:', port)
Canvas fingerprints and profile consistency
Websites spot multi-account automation by probing the HTML5 canvas API. Anti-bot scripts draw hidden 2D shapes, text glyphs and gradients off-screen, then read the pixel buffer with toDataURL() or getImageData(). Differences in hardware rasterization and drivers produce a distinct checksum.
In multi-account automation, two canvas fingerprint mistakes get accounts banned:
- Identical fingerprints across profiles: If 50 distinct accounts across different proxies share the exact same canvas hash down to the bit, bot detection flags the fleet as a single machine.
- Volatile fingerprints within a profile: If a single account returns a different canvas hash on every request, fraud algorithms flag the session for active browser tampering.
Multilogin handles this by injecting deterministic noise into the canvas rendering pipeline. Each profile gets a unique, persistent noise seed. Profile A always returns canvas hash A across reboots, and Profile B returns canvas hash B.
The noise injection runs inside the custom browser binary. So your Puppeteer scripts don't need to patch HTMLCanvasElement.prototype or inject brittle JavaScript shims before page scripts run.
Browser tools that find things by meaning
Hardcoded CSS selectors are fragile on modern web apps. Sites scramble class names, reshuffle the DOM, or run A/B tests that break scripts.
So instead of targeting #submit-btn-v3, the agent inspects the DOM with semantic tools that search by text content, ARIA attributes and interactive elements.
LLM client configuration
First, set up the reasoning model. OpenAI or Google Gemini both work:
import { ChatOpenAI } from '@langchain/openai'

// Create OpenAI model
const llm = new ChatOpenAI({
  modelName: 'gpt-4o-mini',
  temperature: 0,
  openAIApiKey: process.env.OPENAI_API_KEY,
})

// Or use Gemini
import { ChatGoogleGenerativeAI } from '@langchain/google-genai'

const llm = new ChatGoogleGenerativeAI({
  model: 'gemini-2.0-flash',
  temperature: 0,
  apiKey: process.env.GEMINI_API_KEY,
})
Browser interaction tools
Next, give the agent its tools. The most important one is find_elements_by_text, which uses XPath to find elements by their visible label. For tricky UIs where an overlay steals the click, force_click dispatches the click straight through JavaScript.
import { DynamicStructuredTool } from '@langchain/core/tools'
import { z } from 'zod'

const tools = [
  // Navigate to URL
  new DynamicStructuredTool({
    name: 'navigate',
    description: 'Navigate to a URL',
    schema: z.object({
      url: z.string().url(),
    }),
    func: async ({ url }) => {
      await page.goto(url, { waitUntil: 'networkidle2', timeout: 30000 })
      return `Navigated to ${url}`
    },
  }),

  // Click element
  new DynamicStructuredTool({
    name: 'click_element',
    description: 'Click element by CSS selector',
    schema: z.object({
      selector: z.string(),
    }),
    func: async ({ selector }) => {
      await page.waitForSelector(selector, { visible: true, timeout: 10000 })
      await page.click(selector)
      return `Clicked ${selector}`
    },
  }),

  // Type text
  new DynamicStructuredTool({
    name: 'type_text',
    description: 'Type text into an element',
    schema: z.object({
      selector: z.string(),
      text: z.string(),
    }),
    func: async ({ selector, text }) => {
      await page.waitForSelector(selector)
      await page.click(selector)
      await page.keyboard.type(text)
      return `Typed: ${text}`
    },
  }),

  // Press keys
  new DynamicStructuredTool({
    name: 'press_keys',
    description: 'Press keyboard keys',
    schema: z.object({
      keys: z.string(),
    }),
    func: async ({ keys }) => {
      await page.keyboard.press(keys)
      return `Pressed: ${keys}`
    },
  }),

  // Get page info
  new DynamicStructuredTool({
    name: 'get_page_info',
    description: 'Get current page information',
    schema: z.object({}),
    func: async () => {
      return `URL: ${page.url()}, Title: ${await page.title()}`
    },
  }),

  // Find elements by text content (essential for AI-driven automation)
  new DynamicStructuredTool({
    name: 'find_elements_by_text',
    description: 'Find elements containing specific text. Returns selectors for matching elements.',
    schema: z.object({
      text: z.string().describe('Text to search for'),
      tag: z.string().optional().describe('Optional HTML tag to filter (e.g., "button", "div")'),
    }),
    func: async ({ text, tag }) => {
      const elements = await page.evaluate(
        ({ searchText, tagFilter }) => {
          const xpath = tagFilter
            ? `//${tagFilter}[contains(text(), "${searchText}")]`
            : `//*[contains(text(), "${searchText}")]`
          const result = document.evaluate(
            xpath,
            document,
            null,
            XPathResult.ORDERED_NODE_SNAPSHOT_TYPE,
            null
          )
          const found: string[] = []
          for (let i = 0; i < Math.min(result.snapshotLength, 5); i++) {
            const el = result.snapshotItem(i) as HTMLElement
            found.push(
              `${el.tagName.toLowerCase()}${el.className ? '.' + el.className.split(' ').join('.') : ''}`
            )
          }
          return found
        },
        { searchText: text, tagFilter: tag }
      )
      return elements.length > 0
        ? `Found ${elements.length} elements: ${elements.join(', ')}`
        : `No elements found containing "${text}"`
    },
  }),

  // Force click (for stubborn elements like Facebook's Post button)
  new DynamicStructuredTool({
    name: 'force_click',
    description: 'Force click an element using JavaScript. Use when regular click fails.',
    schema: z.object({
      selector: z.string().describe('CSS selector to click'),
    }),
    func: async ({ selector }) => {
      await page.waitForSelector(selector, { visible: true, timeout: 10000 })
      await page.evaluate((sel) => {
        const el = document.querySelector(sel) as HTMLElement
        if (el) el.click()
      }, selector)
      return `Force-clicked ${selector}`
    },
  }),
]
Compiling the ReAct reasoning agent
Put the model and the tools together in a LangGraph ReAct agent. It runs a loop: observe the DOM, pick an action, call the tool, check the updated page.
import { createReactAgent } from '@langchain/langgraph/prebuilt'

// Create ReAct agent (Reasoning + Acting)
const agent = createReactAgent({
  llm,
  tools,
})
Prompts in phases, so the agent doesn't wander
Complex web apps need structured guidance. Without clear constraints, an agent can loop between inputs or submit too early.
So I split the task instructions into explicit phases. Each phase tells the agent what to check before it moves on.
function buildPostingTaskPrompt(content: string): string {
  return `You are an autonomous browser agent controlling a logged-in Facebook session.

=== OBJECTIVE ===
Publish the following content as a new post on Facebook:

${content}

=== EXECUTION STRATEGY ===

PHASE 0: NAVIGATE TO FACEBOOK
- Use: navigate("https://www.facebook.com")
- Wait for page to load
- Verify you're on facebook.com using get_page_info()

PHASE 1: LOCATE POST COMPOSER
- Search for composer using find_elements_by_text("What's on your mind")
- Verify element is visible and clickable

PHASE 2: OPEN COMPOSER MODAL
- Click the composer trigger
- Wait for modal to load (up to 10 seconds)
- Confirm modal is open

PHASE 3: ENTER CONTENT
- Locate text input with contenteditable="true"
- Click inside editor to focus
- Type the content exactly
- Verify text appears

PHASE 4: SUBMIT POST
- Wait 2-3 seconds after typing
- Use: force_click("div[role='dialog'] div[aria-label='Post'][role='button']")
- Alternative: press_keys("Control+Enter")

PHASE 5: VERIFY SUCCESS
- Wait 3 seconds after clicking Post
- Check if modal closed
- Declare success and STOP

=== CORE PRINCIPLES ===
1. ALWAYS use find_elements_by_text() over CSS selectors
2. Wait for elements before interacting (3-5 second timeouts)
3. If an action fails, retry up to 3 times with 2-second delays
4. Stay within facebook.com
5. Think step-by-step and verify each action

Begin execution now.`
}
Runtime task execution and latency monitoring
The task executor runs the agent graph, records how long it took and pulls out token usage.
async function publishFacebookStatus(content: string) {
  try {
    const startTime = Date.now()

    // Invoke the agent
    const result = await agent.invoke({
      messages: [
        {
          role: 'user',
          content: buildPostingTaskPrompt(content),
        },
      ],
    })

    const duration = Date.now() - startTime

    // Extract token usage (if available)
    const lastMessage = result.messages[result.messages.length - 1]
    const tokenUsage = lastMessage?.usage_metadata

    console.log('Task completed successfully:', {
      steps: result.messages.length,
      duration: `${duration}ms`,
      tokenUsage,
    })

    return {
      success: true,
      output: lastMessage?.content,
      steps: result.messages.length,
      duration,
      tokenUsage,
    }
  } catch (error) {
    console.error('Task failed:', error)
    return {
      success: false,
      error: error.message,
    }
  }
}
Cleaning up after crashes
In long-running automation, browsers crash, proxy connections drop and DOM changes cause timeouts.
If a worker exits without stopping its profile, you get two production problems:
- Profile lock contention: The Multilogin launcher maintains a file lock on the profile directory. Subsequent jobs targeting that profile fail immediately with lock errors.
- Resource leakage: Orphaned browser processes consume CPU and RAM until the host machine runs out of memory.
The cure is strict cleanup with try / finally. Even when an agent run fails or throws, the script closes the Puppeteer CDP connection and tells the Multilogin launcher to stop the profile and release the file lock.
Here's the complete production pipeline:
import puppeteer, { Browser, Page } from 'puppeteer-core'
import axios from 'axios'
import { ChatOpenAI } from '@langchain/openai'
import { DynamicStructuredTool } from '@langchain/core/tools'
import { createReactAgent } from '@langchain/langgraph/prebuilt'
import { z } from 'zod'

// Multilogin API helpers
async function getToken(email: string, password: string): Promise<string> {
  const response = await axios.post('https://api.multilogin.com/user/signin', {
    email,
    password, // Sent securely over HTTPS
  })
  return response.data.data.token
}

async function launchProfile(
  token: string,
  folderId: string,
  profileId: string
): Promise<{ port: number }> {
  const url = `https://launcher.mlx.yt:45001/api/v2/profile/f/${folderId}/p/${profileId}/start?automation_type=puppeteer&headless_mode=false`
  const response = await axios.get(url, {
    headers: { Authorization: `Bearer ${token}` },
  })
  return response.data.data
}

async function stopProfile(token: string, profileId: string): Promise<void> {
  await axios.get(`https://launcher.mlx.yt:45001/api/v2/profile/stop/p/${profileId}`, {
    headers: { Authorization: `Bearer ${token}` },
  })
}

// Create browser tools for LangChain
function createBrowserTools(page: Page) {
  return [
    new DynamicStructuredTool({
      name: 'navigate',
      description: 'Navigate to a URL',
      schema: z.object({ url: z.string().url() }),
      func: async ({ url }) => {
        await page.goto(url, { waitUntil: 'networkidle2', timeout: 30000 })
        return `Navigated to ${url}`
      },
    }),
    new DynamicStructuredTool({
      name: 'click_element',
      description: 'Click element by CSS selector',
      schema: z.object({ selector: z.string() }),
      func: async ({ selector }) => {
        await page.waitForSelector(selector, { visible: true, timeout: 10000 })
        await page.click(selector)
        return `Clicked ${selector}`
      },
    }),
    new DynamicStructuredTool({
      name: 'type_text',
      description: 'Type text into an element',
      schema: z.object({ selector: z.string(), text: z.string() }),
      func: async ({ selector, text }) => {
        await page.waitForSelector(selector)
        await page.click(selector)
        await page.keyboard.type(text)
        return `Typed: ${text}`
      },
    }),
  ]
}

async function postFacebookStatus({
  folderId,
  profileId,
  content,
}: {
  folderId: string
  profileId: string
  content: string
}) {
  let browser: Browser | null = null
  let token: string | null = null

  try {
    // Authenticate with Multilogin control plane
    token = await getToken(process.env.MULTILOGIN_EMAIL!, process.env.MULTILOGIN_PASSWORD!)

    // Launch isolated browser profile
    const { port } = await launchProfile(token, folderId, profileId)
    browser = await puppeteer.connect({
      browserWSEndpoint: `ws://127.0.0.1:${port}`,
    })
    const page = await browser.newPage()
    await page.setViewport({ width: 1920, height: 1080 })

    console.log('✓ Browser profile launched')

    // Initialize reasoning model
    const llm = new ChatOpenAI({
      modelName: process.env.AI_MODEL || 'gpt-4o-mini',
      temperature: 0,
    })

    // Register browser interaction tools
    const tools = createBrowserTools(page)

    // Compile ReAct agent
    const agent = createReactAgent({ llm, tools })

    console.log('✓ AI agent initialized')

    // Execute task with phased prompt
    const taskPrompt = buildPostingTaskPrompt(content)
    const result = await agent.invoke({
      messages: [{ role: 'user', content: taskPrompt }],
    })

    console.log('✓ Post published successfully')

    return {
      success: true,
      steps: result.messages.length,
    }
  } catch (error: any) {
    console.error('✗ Failed:', error.message)
    throw error
  } finally {
    // Crash recovery: always disconnect CDP and stop launcher profile
    if (browser) await browser.close()
    if (token) await stopProfile(token, profileId)
    console.log('✓ Browser closed')
  }
}

// Usage
postFacebookStatus({
  folderId: 'your-folder-id',
  profileId: 'your-profile-id',
  content: 'Hello from automated posting!',
})
Concurrency management and multi-account pools
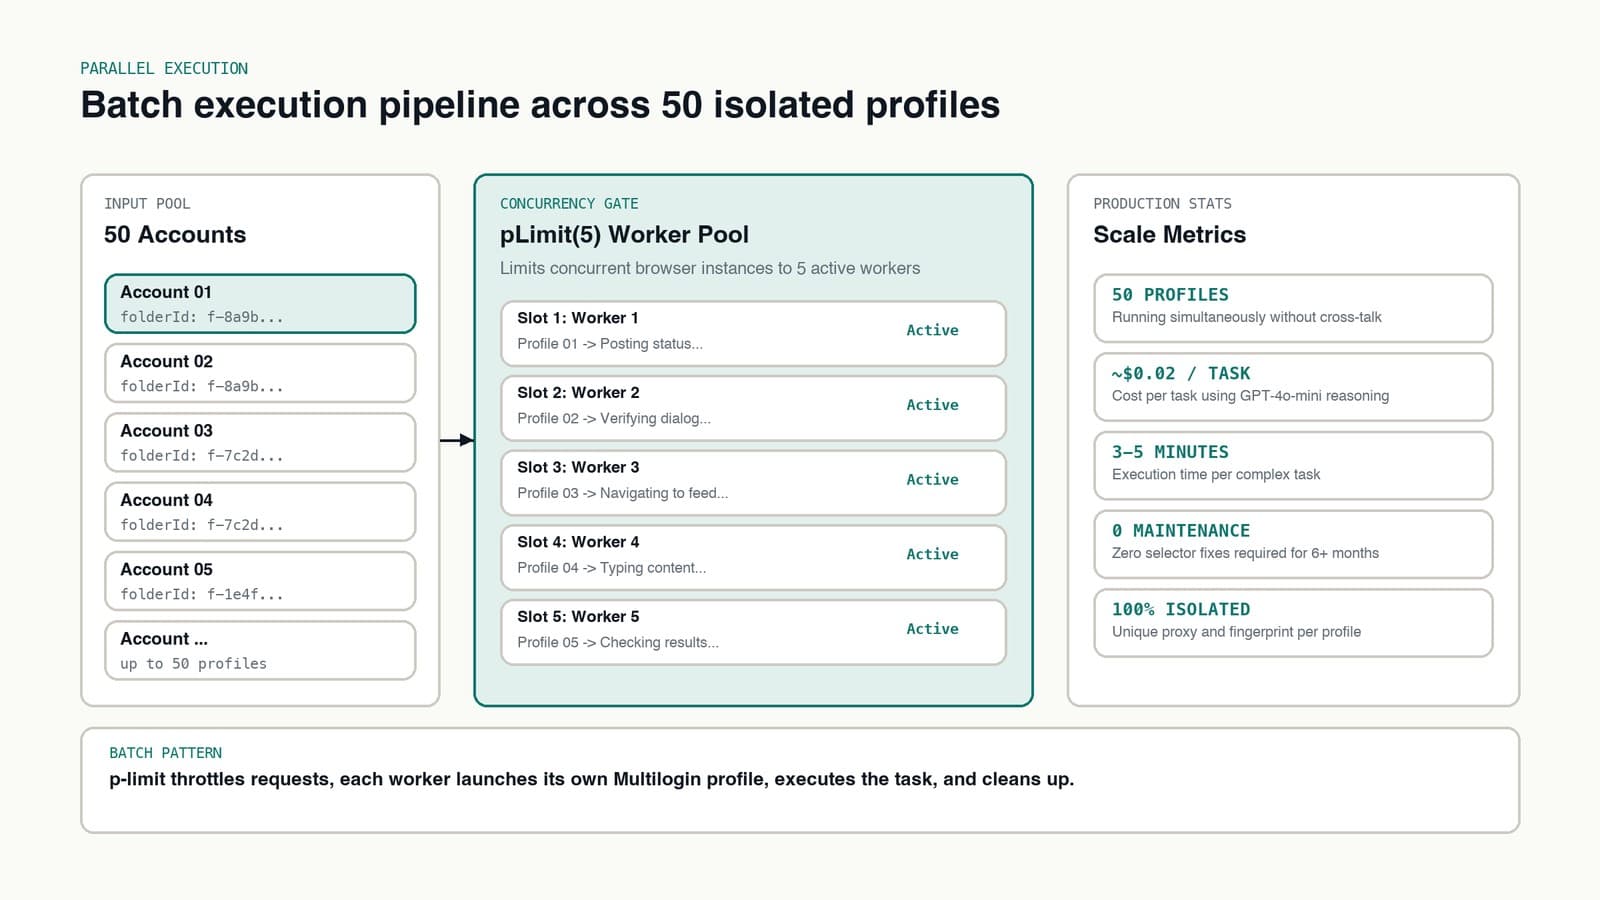
Dozens of browsers at once will eat all your memory if nothing holds them back. p-limit caps how many profiles run at the same time:
import pLimit from 'p-limit'

const limit = pLimit(5) // Max 5 concurrent posts

const accounts = [
  { folderId: '...', profileId: '...' },
  { folderId: '...', profileId: '...' },
  // ... more accounts
]

const tasks = accounts.map((account) =>
  limit(() =>
    postFacebookStatus({
      ...account,
      content: 'Batch post content',
    })
  )
)

const results = await Promise.all(tasks)
Operational costs and performance metrics
Here's what this setup handles in practice:
// Run 50 tasks in parallel, each with isolated browser profile
const accounts = await getAccountProfiles() // Your 50 profiles

const results = await Promise.all(
  accounts.map((account) =>
    limit(() =>
      runAgentTask({
        profile: account,
        task: 'Check notifications and summarize any important messages',
      })
    )
  )
)

console.log(`Processed ${results.length} accounts in parallel`)
Production numbers from this setup:
- 50 profiles running concurrently
- ~$0.02 per task with GPT-4o-mini
- 3 to 5 minutes per complex task
- Zero selector maintenance across six months
Trade-offs and architectural fit
Good fit for:
- Sites that update UI layouts or run active A/B tests
- Managing multiple distinct accounts across social and advertising platforms
- End-to-end testing across distinct user roles and authentication states
- Data collection and competitive pricing audits
- Ad verification across regional proxies
Poor fit for:
- Static sites with immutable HTML elements
- One-off throwaway scripts
- Latency-sensitive flows requiring sub-second responses (AI decisions add 2 to 5 seconds per step)
Architecture extensions
Where I'd take it next:
- Multi-agent collaboration: Split work between navigation agents and data extraction agents.
- Vision-guided navigation: Pass page screenshots to multimodal models when the DOM is obfuscated.
- Self-healing selectors: Cache working selectors and fall back to the LLM only when an element query fails.
The takeaway: when the web keeps changing under your scripts, an agent that reads the page is a practical way to keep up at scale.
Resources
Related posts
- LangGraph browser agents on Puppeteer: prune the DOM, then act
A LangGraph agent that drives Puppeteer over CDP: prune the DOM before the model sees it, fill forms in one batched action, and fall back when a selector breaks.
- Four OpenTabs plugins for Facebook, Greenhouse, Toptal and Upwork
Four open-source OpenTabs plugins give a terminal agent 22 tools in my logged-in Chrome to triage friend requests, fill job forms and update freelance profiles.
- Puppeteer in production: fallback selectors, real waits, clean exits
A Facebook class rename stopped 100+ accounts from posting. The fix: ARIA selectors, real waits, finally cleanup, a lock per account and screenshots on error.