- Published on
Puppeteer in production: fallback selectors, real waits, clean exits
- Authors

- Name
- Nadim Tuhin
- @nadimtuhin
On this page
My first Puppeteer script worked perfectly. Until it didn't.
Facebook changed one class name, and 100+ accounts stopped posting. I spent the weekend rewriting everything with fallback selectors, proper waits, and cleanup handlers.
That weekend I realized the difference between "works on my machine" and "works in production." This guide is the playbook I wish I'd had.
TL;DR: the 5 rules
| Rule | Anti-Pattern | Better Pattern |
|---|---|---|
| Selectors | .x1heo9i (obfuscated) | [aria-label="Post"] or text-based |
| Waits | waitForTimeout(5000) | waitForSelector({ visible: true }) |
| Cleanup | No finally block | Always finally { browser.close() } |
| Sessions | Shared page state | Fresh page per task + distributed locks |
| Debugging | Silent failures | Screenshots + HTML on every error |
Note: This guide uses Puppeteer examples. For new projects, consider Playwright, which has better defaults and API design. On headless mode: since Puppeteer v22,
headless: true(the default) launches the new headless mode, andheadless: 'shell'gives you the old one.headless: 'new'was only needed on older versions.
The rest is code and production patterns from automating Facebook Marketplace (100+ accounts), vehicle uploads, and message pipelines.
Selector strategies
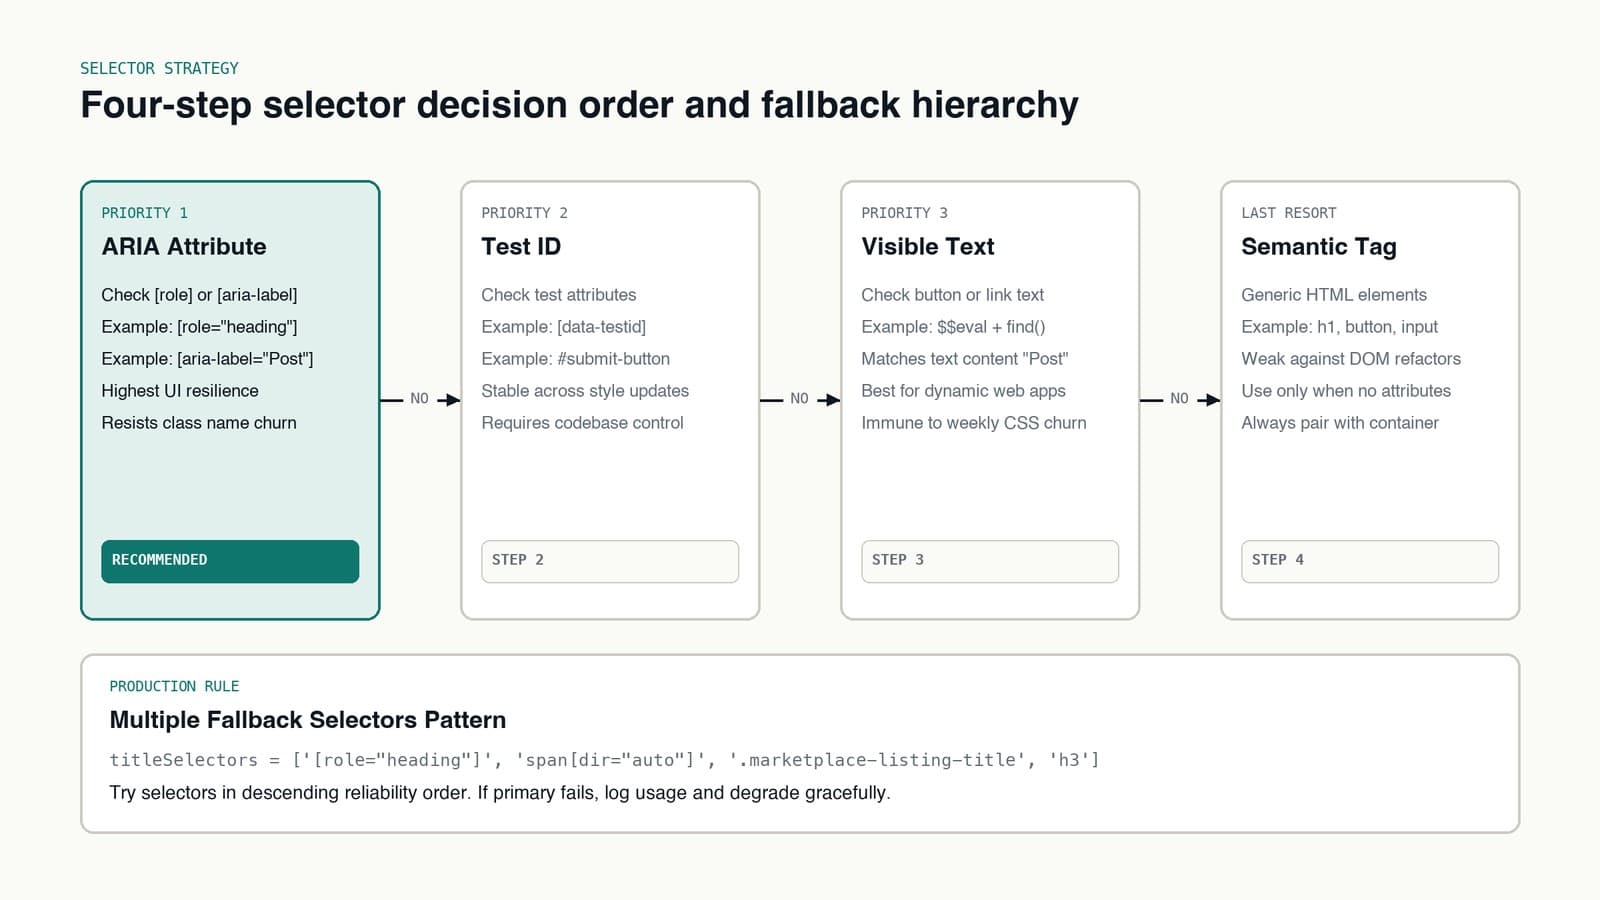
Selector decision flowchart
Decision order (try each in sequence):
Has ARIA attribute? (
[role],[aria-label], etc.)- Yes -> Use ARIA selector (e.g.,
[role="heading"]) - No -> Continue to step 2
- Yes -> Use ARIA selector (e.g.,
Has test ID? (
[data-testid],#id)- Yes -> Use test ID (e.g.,
#submit-button) - No -> Continue to step 3
- Yes -> Use test ID (e.g.,
Has stable text?
- Yes -> Use text-based discovery (
$$eval+find) - No -> Continue to step 4
- Yes -> Use text-based discovery (
Last resort -> Use semantic tags (
h1,button,input, etc.)
Whichever strategy you pick, always add fallback selectors as a backup.
CSS selectors vs text-based discovery
CSS selectors: fast, and reliable when the structure is stable.
// ✅ GOOD - Stable semantic selector
const title = await page.$eval('[role="heading"]', (el) => el.textContent)

// ✅ GOOD - Test ID selector
const button = await page.$eval('#submit-button', (el) => el.click())

// ❌ BAD - Obfuscated class (Facebook does this)
const title = await page.$eval('.x1heo9i .x1gj2m3', (el) => el.textContent)
Text-based discovery: best for dynamic UIs (Facebook, Instagram).
// ✅ GOOD - Find by visible text (runs in browser context, returns serializable data)
const postButtonExists = await page.$$eval('button', (buttons) =>
  buttons.some((btn) => btn.textContent.includes('Post'))
)

// ✅ GOOD - Click element by text content
const clicked = await page.$$eval('button', (buttons) => {
  const btn = buttons.find((b) => b.textContent.includes('Post'))
  if (btn) {
    btn.click()
    return true
  }
  return false
})

// ❌ BAD - Brittle class name
const button = await page.$('.x78zum5') // Changes weekly
Pattern: multiple fallback selectors
Never bet everything on one selector:
// Strategy: Try selectors in order of reliability
const titleSelectors = [
  '[role="heading"]', // Most reliable (ARIA)
  'span[dir="auto"]', // Common Facebook pattern
  '.marketplace-listing-title', // Class-based (brittle)
  'h3', // Last resort
]

let title = null
let usedSelector = null

for (const selector of titleSelectors) {
  const element = await page.$(selector)
  if (element) {
    title = await page.evaluate((el) => el.textContent, element)
    usedSelector = selector
    break
  }
}

if (!title) {
  // Graceful degradation - don't crash
  console.warn('Title not found, tried:', titleSelectors.join(', '))
  title = 'Unknown'
}

// Log for debugging selector effectiveness
logSelectorUsage('title', usedSelector)
Anti-pattern: hardcoded classes
// ❌ NEVER DO THIS - Facebook classes change daily
const postButton = await page.$('.x1heo9i.x1gj2m3')

// ✅ INSTEAD - Use ARIA attributes
const postButton = await page.$('[aria-label="Post"]')

// ✅ OR - Use text discovery (evaluate in browser context)
const clicked = await page.$$eval('button', (buttons) => {
  const btn = buttons.find((b) => b.textContent.includes('Post'))
  if (btn) {
    btn.click()
    return true
  }
  return false
})
Pattern: wait for element before interaction
// ❌ WRONG - No wait, race condition
await page.click('#submit')

// ✅ CORRECT - Wait for visibility
await page.waitForSelector('#submit', { visible: true, timeout: 10000 })
await page.click('#submit')

// ✅ BETTER - Wait and click directly (waitForSelector already confirms existence)
await page.waitForSelector('#submit', {
  visible: true,
  timeout: 10000,
})
await page.click('#submit')
Wait strategies
Explicit vs implicit waits
Explicit waits: say exactly what you're waiting for.
// ✅ GOOD - Explicit wait for specific condition
await page.waitForSelector('[aria-label="Loading"]', {
  hidden: true,
  timeout: 30000,
})

// ✅ GOOD - Explicit wait for navigation (modern pattern)
await page.click('a[href="/next"]')
await page.waitForNavigation({ waitUntil: 'networkidle2' })

// ✅ GOOD - Wait for custom condition
await page.waitForFunction(() => document.querySelector('[data-loaded]') !== null, {
  timeout: 10000,
})
Implicit waits: guess what the browser is doing. Avoid these.
// ❌ BAD - Guessing delay
await page.click('#submit')
await new Promise((resolve) => setTimeout(resolve, 3000)) // Hope it's done

// ❌ BAD - Fixed timeout regardless of state
await page.waitForTimeout(5000) // Might wait too long or not enough

// ❌ BAD - Assumed state
await page.click('#submit')
const nextButton = await page.$('#next') // Might not exist yet
Pattern: wait for success indicator
Wait for real success, not a fixed timeout:
// ❌ BAD - Hope post completes in 10 seconds
await page.click('#post')
await page.waitForTimeout(10000)

// ✅ GOOD - Wait for actual success message
await page.click('#post')
await page.waitForSelector('[aria-label="Success notification"]', {
  visible: true,
  timeout: 30000,
})

// ✅ BEST - Wait for success AND verify URL change
const postClickPromise = page.click('#post')
const successPromise = page.waitForSelector('[data-success="true"]')
const urlPromise = page.waitForNavigation()

await Promise.all([postClickPromise, successPromise, urlPromise])
Pattern: wait for multiple conditions
Complex workflows often need more than one condition:
// Upload form scenario
await Promise.all([
  // Wait for upload progress to appear
  page.waitForSelector('[aria-label="Uploading"]'),

  // Wait for file input to be filled
  page.waitForFunction(() => {
    const input = document.querySelector('input[type="file"]')
    return input && input.files.length > 0
  }),

  // Wait for submit button to be enabled
  page.waitForSelector('button:not([disabled])'),
])

// All conditions must be met before continuing
Anti-pattern: waitForTimeout
// ❌ AVOID - Unreliable magic numbers
await page.click('#submit')
await page.waitForTimeout(5000) // Why 5 seconds? What if it takes 6?

// ❌ AVOID - No verification
await page.type('#email', 'user@example.com')
await page.waitForTimeout(1000)
await page.type('#password', 'password') // Did email input work?
Pattern: exponential backoff for polling
For conditions that take unpredictable time:
async function waitForWithBackoff(page, condition, maxAttempts = 10, baseDelay = 1000) {
  for (let attempt = 1; attempt <= maxAttempts; attempt++) {
    try {
      const result = await condition()
      if (result) {
        return result
      }
    } catch (error) {
      // Condition might throw, try again
    }

    const delay = baseDelay * Math.pow(2, attempt - 1)
    console.log(`Attempt ${attempt}/${maxAttempts}, retrying in ${delay}ms`)
    await new Promise((resolve) => setTimeout(resolve, delay))
  }

  throw new Error(`Condition not met after ${maxAttempts} attempts`)
}

// Usage
const result = await waitForWithBackoff(
  page,
  async () => {
    const text = await page.$eval('[data-status]', (el) => el.textContent)
    return text === 'complete' ? text : null
  },
  15, // max attempts
  1000 // 1 second base delay
)
Resource cleanup patterns
A script that throws halfway through still owns a browser. If nothing closes it, zombie Chrome processes pile up until the machine runs out of memory. Cleanup has to run on every path, not just the happy one.
Pattern: always cleanup in finally block
// ❌ WRONG - Browser might leak if exception thrown
await page.goto('https://example.com')
await page.click('#button')
await browser.close() // Never reached if click fails

// ✅ CORRECT - Guaranteed cleanup
let browser
try {
  browser = await puppeteer.launch()
  const page = await browser.newPage()
  await page.goto('https://example.com')
  await page.click('#button')
} finally {
  if (browser) {
    await browser.close()
  }
}
Pattern: track and close all pages
// Track opened pages
const pages = []

async function safeNavigate(url) {
  const page = await browser.newPage()
  pages.push(page)

  try {
    await page.goto(url)
    return page
  } catch (error) {
    await page.close()
    throw error
  }
}

// Cleanup all pages
async function cleanup() {
  await Promise.all(pages.map((page) => page.close()))
  pages.length = 0
}

// Usage
try {
  const page1 = await safeNavigate('https://example.com/page1')
  const page2 = await safeNavigate('https://example.com/page2')
  // Do work
} finally {
  await cleanup()
}
Pattern: close connections and streams
// ❌ WRONG - Buffer not handled properly
const screenshot = await page.screenshot()
// screenshot is a Buffer, use it directly

// ✅ CORRECT - Save screenshot to file
await page.screenshot({ path: 'screenshot.png', fullPage: true })

// ✅ CORRECT - Use buffer directly
const screenshotBuffer = await page.screenshot({ fullPage: true })
await fs.writeFile('screenshot.png', screenshotBuffer)
Pattern: profile cleanup for Multilogin
async function scrapeWithProfile(profileId, folderId) {
  let browser
  let profile

  try {
    // Launch profile
    profile = await startProfile(profileId, folderId)
    browser = await puppeteer.connect({
      browserURL: profile.browserUrl,
    })

    // Do work
    const data = await scrapeData(browser)

    return data
  } catch (error) {
    console.error('Scraping failed:', error)
    throw error
  } finally {
    // Always cleanup
    if (browser) {
      try {
        await browser.close()
      } catch (closeError) {
        console.error('Failed to close browser:', closeError)
      }
    }

    if (profile) {
      try {
        await stopProfile(profileId)
      } catch (stopError) {
        console.error('Failed to stop profile:', stopError)
      }
    }
  }
}
Anti-pattern: nested try-catch without finally
// ❌ WRONG - Cleanup might not run
try {
  const browser = await puppeteer.launch()
  try {
    const page = await browser.newPage()
    await page.goto('https://example.com')
  } catch (error) {
    console.error('Page error:', error)
  }
  // browser.close() only runs if no exception
  await browser.close()
}

// ✅ CORRECT - Single finally for all cleanup
let browser
let page
try {
  browser = await puppeteer.launch()
  page = await browser.newPage()
  await page.goto('https://example.com')
} catch (error) {
  console.error('Error:', error)
} finally {
  if (page) await page.close()
  if (browser) await browser.close()
}
Session management
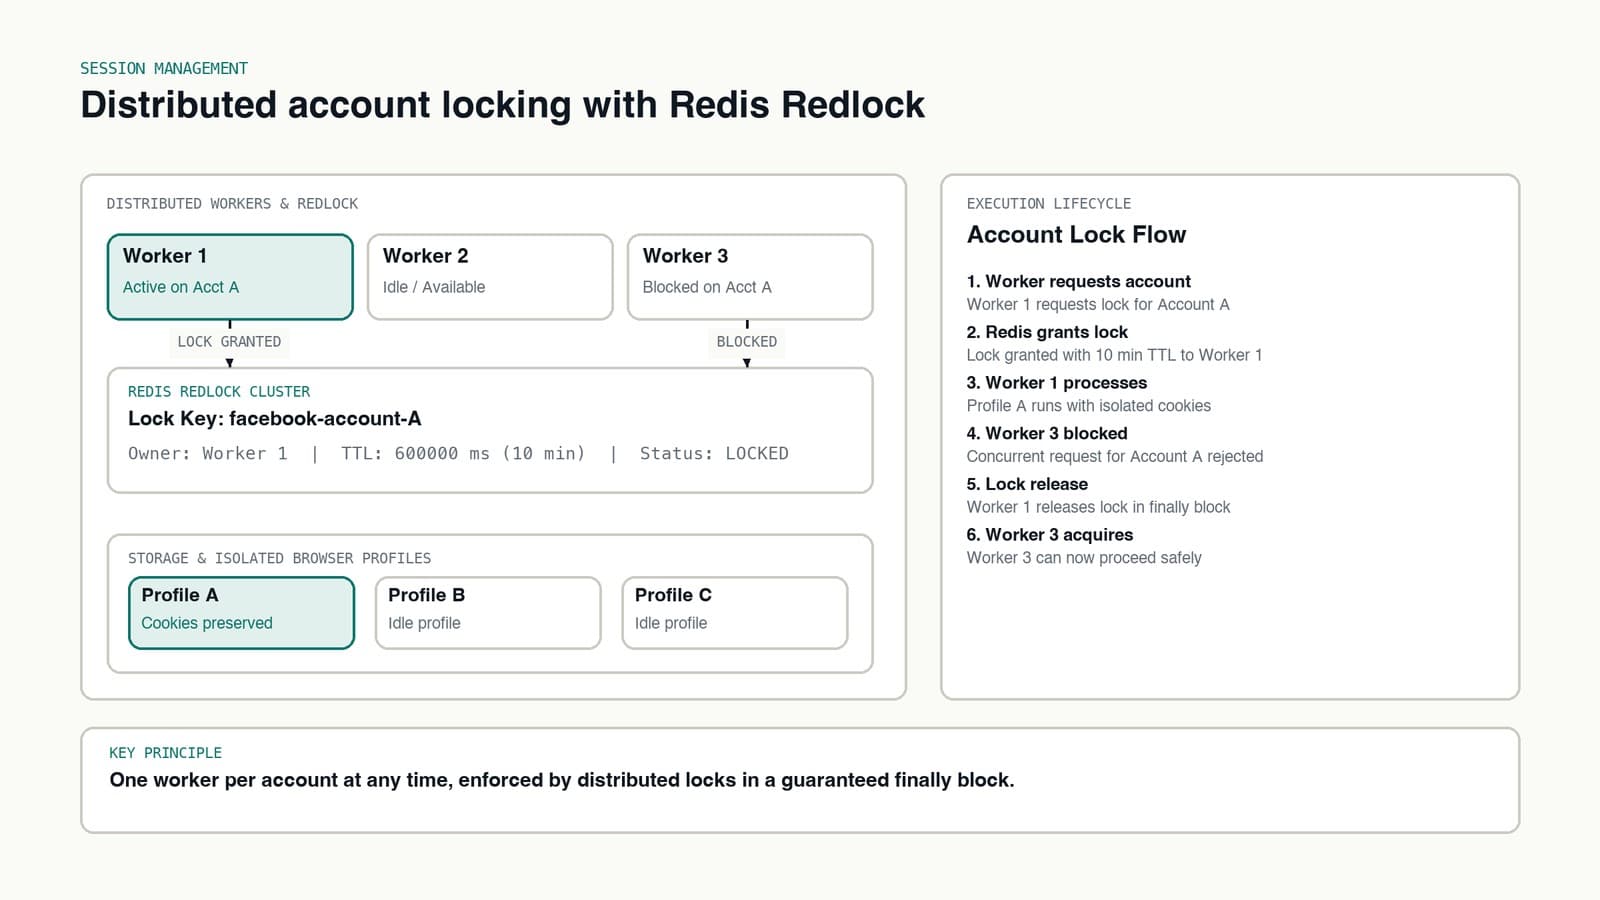
Session management architecture
| Layer | Component | Description |
|---|---|---|
| Workers | Worker 1, 2, 3 | Parallel processes handling accounts |
| Locking | Redis Redlock | Distributed locks with TTL (e.g., 10min) |
| Storage | Browser Profiles | Isolated cookies & localStorage per account |
Flow:
- Worker requests account -> Worker 1 wants Account A
- Acquire lock -> Redis grants lock (Owner: W1, TTL: 10min)
- Process account -> Worker 1 uses Profile A (cookies preserved)
- Concurrent request blocked -> Worker 3 wants Account A -> BLOCKED (already locked)
- Release lock -> Worker 1 finishes, releases lock
- Next worker proceeds -> Worker 3 can now acquire Account A
Key principle: One worker per account at any time, enforced by distributed locks.
Pattern: use distributed locks per account
import { redlock } from 'src/lib/redlock'

async function processAccount(accountId, task) {
  const lockKey = `facebook-account-${accountId}`
  const lockTTL = 600000 // 10 minutes

  let lock
  try {
    // Acquire lock
    lock = await redlock.acquire([lockKey], lockTTL)

    // Only one worker processes this account
    const profile = await getProfile(accountId)
    await task(profile)
  } catch (error) {
    if (error.message.includes('Lock')) {
      console.warn(`Account ${accountId} is locked, skipping`)
      return // Another worker is processing it
    }
    throw error
  } finally {
    // Always release lock
    if (lock) {
      await lock.release()
    }
  }
}
Pattern: session expiry and renewal
const SESSION_MAX_AGE = 30 * 60 * 1000 // 30 minutes

async function getActiveSession(accountId) {
  // Check cached session
  const cached = await cache.get(`session:${accountId}`)
  if (cached) {
    const age = Date.now() - cached.createdAt
    if (age < SESSION_MAX_AGE) {
      return cached // Session still valid
    }
    // Session expired
    console.log(`Session for ${accountId} expired`)
    await cache.del(`session:${accountId}`)
  }

  // Create new session
  const session = await createNewSession(accountId)
  await cache.set(`session:${accountId}`, session, { ttl: SESSION_MAX_AGE })
  return session
}
Pattern: cookie persistence
// Save cookies after authentication
async function authenticateAndSaveCookies(accountId) {
  const browser = await puppeteer.launch()
  const page = await browser.newPage()

  // Authenticate
  await page.goto('https://facebook.com/login')
  await page.type('#email', account.email)
  await page.type('#pass', account.password)
  await page.click('#loginbutton')
  await page.waitForNavigation()

  // Save cookies
  const cookies = await page.cookies()
  await db.cookies.upsert({
    accountId,
    data: JSON.stringify(cookies),
    updatedAt: new Date(),
  })

  await browser.close()
}

// Restore cookies on next use
async function restoreCookies(accountId, page) {
  const cookieData = await db.cookies.findUnique({
    where: { accountId },
  })

  if (cookieData) {
    const cookies = JSON.parse(cookieData.data)
    await page.setCookie(...cookies)
    await page.goto('https://facebook.com') // Cookies auto-applied
  }
}
Anti-pattern: sharing pages between tasks
// ❌ WRONG - Page state leaks between tasks
const page = await browser.newPage()

async function task1() {
  await page.goto('https://example.com/task1')
  await page.click('#button')
  // Page left at task1's state
}

async function task2() {
  await page.goto('https://example.com/task2')
  // Unexpected state from task1
  // Cookies, localStorage, URL bar affected
}

// ✅ CORRECT - Fresh page per task
async function taskWithFreshPage() {
  const page = await browser.newPage()
  try {
    await page.goto('https://example.com/task1')
    await page.click('#button')
  } finally {
    await page.close()
  }
}
Debugging techniques
Pattern: store raw HTML for debugging
async function scrapeWithDebug(page, accountId) {
  const startTime = Date.now()

  try {
    // Scrape data
    const data = await page.evaluate(() => {
      return {
        title: document.querySelector('h1')?.textContent,
        price: document.querySelector('[data-price]')?.textContent,
      }
    })

    return data
  } catch (error) {
    // Capture full state when error occurs
    const html = await page.content()
    const screenshot = await page.screenshot({ fullPage: true })

    // Store for debugging
    await db.debugLog.create({
      accountId,
      error: error.message,
      html,
      screenshot,
      timestamp: new Date(),
      url: page.url(),
      duration: Date.now() - startTime,
    })

    console.error('Scraping failed, debug ID:', debugLog.id)
    throw error
  }
}
Pattern: screenshot on every step
async function scrapeWithScreenshots(page, sessionId) {
  let step = 0

  const screenshot = async (name) => {
    const path = `debug/${sessionId}-${step}-${name}.png`
    await page.screenshot({ path, fullPage: true })
    step++
    console.log(`Screenshot: ${path}`)
  }

  try {
    await page.goto('https://example.com')
    await screenshot('initial')

    await page.click('#button')
    await screenshot('clicked-button')

    await page.waitForSelector('#result')
    await screenshot('result-loaded')

    return data
  } catch (error) {
    await screenshot('error')
    throw error
  }
}
Pattern: verbose logging with context
class ScraperLogger {
  constructor(accountId, sessionId) {
    this.accountId = accountId
    this.sessionId = sessionId
  }

  log(message, context = {}) {
    console.log({
      timestamp: new Date().toISOString(),
      accountId: this.accountId,
      sessionId: this.sessionId,
      message,
      ...context,
    })
  }

  async logPageState(page, message) {
    const state = await page.evaluate(() => ({
      url: window.location.href,
      title: document.title,
      visible: document.visibilityState,
    }))
    this.log(message, { pageState: state })
  }
}

// Usage
const logger = new ScraperLogger(accountId, sessionId)

await page.goto('https://example.com')
logger.logPageState(page, 'Navigation complete')

await page.click('#button')
logger.log('Clicked button', { selector: '#button' })
Pattern: console logging in browser context
// Add console listeners before page loads
page.on('console', (msg) => {
  if (msg.type() === 'error') {
    console.error('Browser console error:', msg.text())
  }
})

page.on('pageerror', (error) => {
  console.error('Page error:', error.toString())
})

// Navigate and capture JavaScript errors
await page.goto('https://example.com')
Pattern: step-by-step execution for AI agents
async function executeAgentTask(agent, task) {
  const startTime = Date.now()
  const steps = []

  // Log each step
  const logStep = (step, tool, input, output) => {
    steps.push({ step, tool, input, output, timestamp: Date.now() })
    console.log(`Step ${step}: ${tool}(${JSON.stringify(input)})`)
    console.log(`  -> ${output}`)
  }

  try {
    const result = await agent.executeTask(task, {
      callbacks: [
        {
          handleToolStart: (tool, input) => {
            logStep(steps.length + 1, tool.name, input)
          },
          handleToolEnd: (output) => {
            if (steps.length > 0) {
              steps[steps.length - 1].output = String(output)
            }
          },
        },
      ],
    })

    const duration = Date.now() - startTime

    // Save execution trace
    await db.agentExecution.create({
      task,
      steps,
      duration,
      success: result.success,
      timestamp: new Date(),
    })

    return result
  } catch (error) {
    // Save failed execution
    await db.agentExecution.create({
      task,
      steps,
      error: error.message,
      timestamp: new Date(),
    })
    throw error
  }
}
Anti-pattern: silent failures
// ❌ WRONG - Errors swallowed
async function scrape() {
  try {
    await page.goto('https://example.com')
    const data = await page.evaluate(() => document.querySelector('h1').textContent)
    return data
  } catch (error) {
    // Silent - no one knows it failed
    return null
  }
}

// ✅ CORRECT - Log and propagate
async function scrape() {
  try {
    await page.goto('https://example.com')
    const data = await page.evaluate(() => document.querySelector('h1').textContent)
    return data
  } catch (error) {
    console.error('Scraping failed:', {
      error: error.message,
      url: page.url(),
      stack: error.stack,
    })
    throw error // Propagate to caller
  }
}
Anti-patterns summary
Selector anti-patterns
| Anti-Pattern | Why It's Bad | Better Alternative |
|---|---|---|
Obfuscated classes (.x1heo9i) | Changes weekly | ARIA attributes ([role="heading"]) |
Hardcoded paths (div > div > span) | Brittle to DOM changes | Flexible selectors with fallbacks |
| No wait before click | Race condition | waitForSelector({ visible: true }) |
| Single selector strategy | Fails if structure changes | Multiple fallback selectors |
Wait anti-patterns
| Anti-Pattern | Why It's Bad | Better Alternative |
|---|---|---|
waitForTimeout(5000) | Magic number, no verification | waitForSelector() with specific element |
| No wait after navigation | Element might not exist | waitForNavigation() or waitForFunction() |
| Assume state (no verification) | Race conditions | Wait for actual success indicator |
Cleanup anti-patterns
| Anti-Pattern | Why It's Bad | Better Alternative |
|---|---|---|
| No finally block | Resources leak on error | Always cleanup in finally |
| Nested try-catch | Cleanup might not run | Single finally for all resources |
| Unclosed streams | Memory leaks | finally { await stream.destroy() } |
Session anti-patterns
| Anti-Pattern | Why It's Bad | Better Alternative |
|---|---|---|
| No account locking | Concurrent operations | Distributed lock per account |
| No session expiry | Stale cookies cause failures | Check and renew sessions |
| Shared page state | Leaks between tasks | Fresh page per task |
Testing patterns
Pattern: visual regression tests
import pixelmatch from 'pixelmatch'
import { PNG } from 'pngjs'
import fs from 'fs'

async function testVisual(page, testName) {
  // Capture current screenshot
  const screenshotBuffer = await page.screenshot()
  const screenshot = PNG.sync.read(screenshotBuffer)

  // Load baseline
  const baselinePath = `baselines/${testName}.png`
  if (!fs.existsSync(baselinePath)) {
    // Create baseline if it doesn't exist
    fs.writeFileSync(baselinePath, screenshotBuffer)
    console.log(`Created baseline: ${baselinePath}`)
    return
  }

  const baseline = PNG.sync.read(fs.readFileSync(baselinePath))

  // Compare images
  const { width, height } = baseline
  const diffImage = new PNG({ width, height })
  const numDiffPixels = pixelmatch(baseline.data, screenshot.data, diffImage.data, width, height, {
    threshold: 0.1,
  })

  if (numDiffPixels > 0) {
    fs.writeFileSync(`diffs/${testName}-diff.png`, PNG.sync.write(diffImage))
    throw new Error(`Visual regression detected for ${testName}: ${numDiffPixels} pixels differ`)
  }
}
Pattern: selector stability tests
async function testSelectorStability(url, selector, retries = 10) {
  const results = []

  for (let i = 0; i < retries; i++) {
    const browser = await puppeteer.launch()
    const page = await browser.newPage()

    const element = await page.$(selector)
    results.push(!!element)

    await browser.close()
  }

  const successRate = results.filter((r) => r).length / retries

  if (successRate < 0.8) {
    console.warn(`Selector ${selector} only ${successRate * 100}% reliable`)
  }

  return successRate
}
My production setup
I've run 100+ browser profiles for months. Here's what actually works:
Stack:
- Multilogin: Isolated browser profiles with unique fingerprints
- Puppeteer: Core automation (considering Playwright for new projects)
- Redis + Redlock: Distributed locks per account
- PostgreSQL: Session/cookie persistence, debug logs
Key Metrics:
- Selector fallback rate: ~15% (fallbacks trigger when primary fails)
- Session reuse rate: ~80% (avoid re-auth when possible)
- Error screenshot capture: 100% (never debug blind)
- Uptime: 99.2% after implementing these patterns
Cost breakdown (monthly):
- Multilogin: ~$100 (100 profiles)
- Proxy bandwidth: ~$50
- Redis/DB hosting: ~$20
- Total: ~$170/month for production-grade automation
Lessons learned:
- Log selector usage: Know which fallbacks fire most often
- Rotate user agents weekly: Even with Multilogin
- Human-like delays: Random 1-3s between actions
- Screenshot on success too: Not just errors (helps verify)
Production reliability patterns
Reliable browser automation comes down to three operational rules:
- Never depend on a single CSS class.
- Always clean up browser processes in
finallyblocks, so zombie Chrome instances don't eat your memory. - Wrap actions in deterministic retry budgets.
The gap between a script that breaks every morning and one that runs unattended is designing for the edge cases up front.
Resources
- Puppeteer Documentation
- Playwright Documentation: Consider for new projects
- ARIA Accessibility Spec: Stable selectors
- Multilogin: Browser fingerprint isolation
- Redlock Algorithm: Distributed locking
Frequently asked questions
- What is the most reliable selector strategy for Puppeteer?
- Prefer ARIA attributes such as [aria-label] or [role], then test IDs, then stable text, and use semantic tags as a last resort. Avoid obfuscated class names like .x1heo9i, which Facebook changes often, and always keep fallback selectors.
- Why should I avoid waitForTimeout in Puppeteer?
- A fixed delay is a magic number that can wait too long or not long enough. Use waitForSelector with visible: true, or wait for a real success indicator, so the script continues as soon as the page is ready.
- How do you stop Puppeteer from leaking browser processes?
- Close the browser and pages in a finally block so cleanup runs even when a step throws. Use a fresh page per task, and for profile-based tools also stop the profile in finally.
- How do you run Puppeteer on many accounts without conflicts?
- Take a distributed lock per account, for example with Redis Redlock and a 10 minute TTL, so only one worker uses an account at a time. Keep isolated browser profiles per account, and capture a screenshot and the HTML on every error so you never debug blind.
Related posts
- LangGraph browser agents on Puppeteer: prune the DOM, then act
A LangGraph agent that drives Puppeteer over CDP: prune the DOM before the model sees it, fill forms in one batched action, and fall back when a selector breaks.
- Driving Multilogin browser profiles with Puppeteer and a LangGraph agent
Connect Puppeteer to Multilogin profiles over CDP and drive them with a LangGraph agent at about $0.02 a task on GPT-4o-mini, with fingerprint checks and clean teardown.
- Scraping: fail loudly when the page layout changes
A scraper that parses nothing and exits 0 looks healthy while it fills your database with gaps. A count check and a saved fixture catch it.