- Published on
Factory Droid on GLM-4.7 and MiniMax M2.1 for cheaper AI coding
- Authors

- Name
- Nadim Tuhin
- @nadimtuhin
On this page
Last month, I was paying $20/month for Claude Pro for daily coding work. It's a good tool. But I kept wondering how much of that work really needed it.
So I went looking for cheaper models, and that led me to Factory's Droid: an AI coding agent that works with any LLM provider.
After trying a few models, I found two that handle everyday coding work at a fraction of the cost. I didn't benchmark them against Claude, so this guide is about price and setup, not a quality ranking. Here it is.
TL;DR
| Provider | Monthly Cost | Where I used it |
|---|---|---|
| GLM-4.7 | $3/month | Daily development, refactoring |
| MiniMax M2.1 | Pay-as-you-go | Backup when others hit rate limits |
| Claude Pro | $20/month | Complex architecture, planning |
Why consider alternatives?
I'm not saying Claude is bad; it's excellent. But:
- Many coding tasks don't need the best model. Simple CRUD, bug fixes, and refactoring work fine with cheaper alternatives.
- Rate limits hurt. When Claude throttles you mid-feature, having a backup matters.
- Different kinds of work, different models. I route different kinds of work to each one (see the table below).
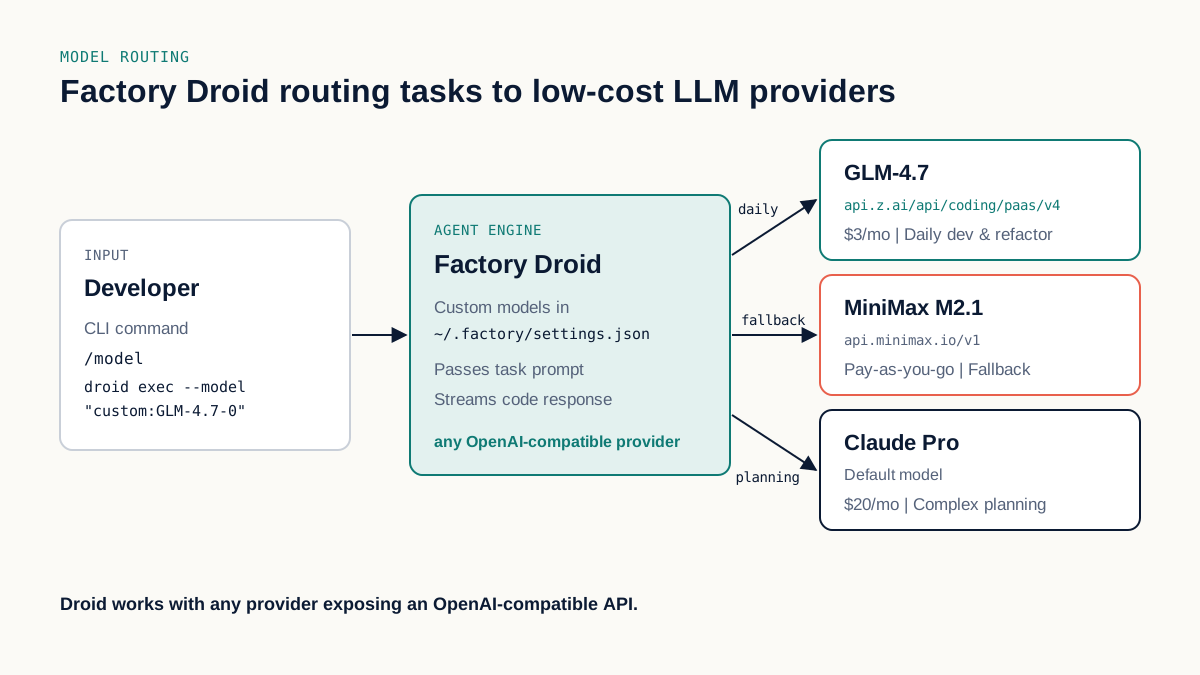
Factory's Droid lets you switch models with /model or per run with --model, so you can use Claude for complex planning and cheaper models for everything else.
Cost comparison
Here's how GLM-4.7 and MiniMax M2.1 compare to Claude's pricing plans:
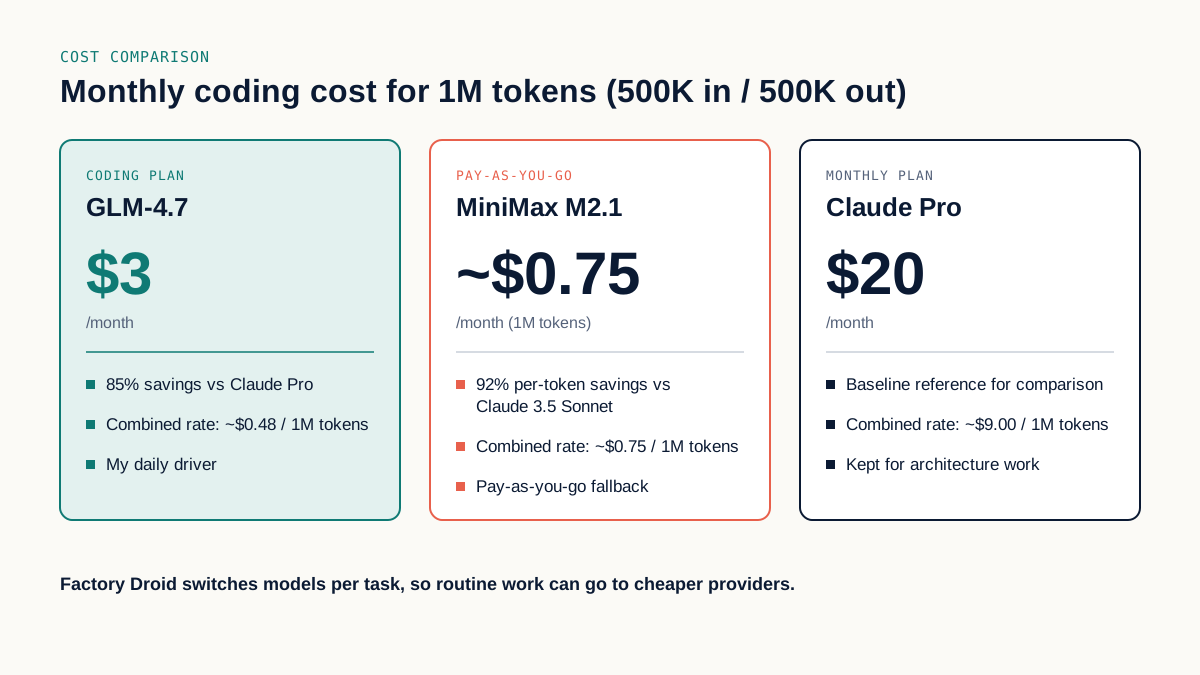
Monthly cost (assuming typical usage)
Typical usage: 500K input tokens + 500K output tokens per month
| Model/Plan | Monthly Cost | Notes |
|---|---|---|
| GLM-4.7 (Coding Plan) | $3 | Subscription with generous limits |
| MiniMax M2.1 (Pay-as-you-go) | ~$0.75 | Based on 1M total tokens |
| Claude Pro | $20 | Monthly subscription |
| Claude Team | $30/user | Minimum 5 members |
Per-token costs
Cost per 1M tokens:
| Model | Input Cost | Output Cost | Combined (50/50) |
|---|---|---|---|
| GLM-4.7 | ~$0.16 | ~$0.80 | ~$0.48 |
| MiniMax M2.1 | ~$0.30 | ~$1.20 | ~$0.75 |
| Claude 3.5 Sonnet | ~$3.00 | ~$15.00 | ~$9.00 |
| Claude 3 Opus | ~$15.00 | ~$75.00 | ~$45.00 |
Key takeaways
GLM-4.7 saves 85-95% vs Claude:
- vs Claude Pro: $3/month vs $20/month (85% savings)
- vs Claude Team: $3/month vs $150/month (98% savings)
- Per-token: $0.48/M vs $9.00/M (95% savings)
MiniMax M2.1 saves 90-92% vs Claude:
- Per-token: $0.75/M vs $9.00/M (92% savings)
- Pay-as-you-go: Only pay for what you use
- No monthly commitment: Suits occasional use
Real-world savings example
Scenario: Developer working on multiple projects, averaging:
- 100 files reviewed per month
- 50 feature implementations per month
- 30 debugging sessions per month
- 20 refactoring tasks per month
Estimated usage: 3M input tokens + 3M output tokens = 6M tokens total
| Provider | Monthly Cost | Annual Cost |
|---|---|---|
| GLM-4.7 | $3 | $36 |
| MiniMax M2.1 | ~$4.50 | ~$54 |
| Claude Pro | $20 | $240 |
| Claude Team | $150 | $1,800 |
Savings per year:
- GLM-4.7 vs Claude Pro: $204/year (85% savings)
- GLM-4.7 vs Claude Team: $1,764/year (98% savings)
- MiniMax M2.1 vs Claude Pro: $186/year (78% savings)
When each makes sense
Use GLM-4.7 ($3/month) when:
- Daily development work
- 2+ projects simultaneously
- Heavy code review and generation
- You want a flat monthly bill
Use MiniMax M2.1 (pay-as-you-go) when:
- Occasional development work
- Testing different models
- Variable monthly workload
- Want maximum cost flexibility
Use Claude Pro ($20/month) when:
- Multi-step complex planning
- Working on complex architectures
- Cost is not the primary factor
Use Claude Team ($30/user/month) when:
- Team collaboration features needed
- Higher rate limits required
- Enterprise compliance needed
Setting up Droid
Installation
Droid is Factory's CLI. On macOS or Linux, install it with Factory's script:
curl -fsSL https://app.factory.ai/cli | sh
Prefer a package manager? Factory also documents brew install --cask droid and npm install -g droid.
Verify installation:
droid --version
Then run droid inside a project and sign in when it asks.
Where custom models live
Droid reads your own models from a customModels array in ~/.factory/settings.json. Each entry needs a model id, a baseUrl, a provider and (for paid APIs) an apiKey. You can also add them from inside Droid: run /model and pick Manage custom models, or open /settings.
For OpenAI-compatible providers like Z.ai and MiniMax, provider is generic-chat-completion-api. The apiKey field can read an environment variable with ${VAR_NAME}, so the key itself never sits in the file:
{
  "customModels": [
    {
      "model": "your-model-id",
      "displayName": "My Custom Model",
      "baseUrl": "https://api.provider.com/v1",
      "apiKey": "${PROVIDER_API_KEY}",
      "provider": "generic-chat-completion-api",
      "maxOutputTokens": 16384
    }
  ]
}
If you still have an old ~/.factory/config.json with snake_case custom_models, Droid copies those models into settings.json on startup. Make any later changes in settings.json.
GLM-4.7 setup
GLM-4.7 is the Z.ai model I ran on the Coding Plan for everyday coding.
Get API key
- Visit Z.ai
- Sign up or login
- Open API Keys and create a key under Personal Coding Plan (Z.ai bills Coding Plan keys and standard API keys separately)
- Export it in your shell:
export ZAI_API_KEY=your-zai-api-key
Configure Droid for GLM-4.7
Z.ai's OpenAI-compatible endpoint for the Coding Plan is https://api.z.ai/api/coding/paas/v4:
{
  "customModels": [
    {
      "model": "glm-4.7",
      "displayName": "GLM-4.7",
      "baseUrl": "https://api.z.ai/api/coding/paas/v4",
      "apiKey": "${ZAI_API_KEY}",
      "provider": "generic-chat-completion-api"
    }
  ]
}
Pricing
GLM-4.7 uses subscription-based pricing:
- Coding Plan: $3/month with generous limits
- Effective rate: ~$0.16/1M input tokens, ~$0.80/1M output tokens
Heads-up: Z.ai has changed its Coding Plan prices and models since I wrote this. Check z.ai/subscribe for today's plans. The config shape stays the same.
What I use it for
Everyday edits, CRUD and small refactors. I didn't benchmark it, so that's how I route work, not a quality ranking.
Using Droid with GLM-4.7
# Interactive coding session, then pick "GLM-4.7" under Custom Models in /model
droid

# Start a session with an initial prompt
droid "Create a REST API with Express"

# One-shot run with the GLM model (custom models use custom:<displayName>-<index>)
droid exec --model "custom:GLM-4.7-0" "Explain src/utils/helpers.js"

# Let it edit files (droid exec is read-only unless you raise autonomy)
droid exec --auto low --model "custom:GLM-4.7-0" "Fix the type errors in src/app.ts"
MiniMax M2.1 setup
MiniMax M2.1 is the model I kept as a pay-as-you-go fallback.
Get API key
- Visit MiniMax
- Register for an account
- Create API key in dashboard
- Export it in your shell:
export MINIMAX_API_KEY=your-minimax-api-key
Configure Droid for MiniMax M2.1
Add it as a second entry in the same customModels array. MiniMax's international OpenAI-compatible endpoint is https://api.minimax.io/v1, and the model id is MiniMax-M2.1:
{
  "customModels": [
    {
      "model": "glm-4.7",
      "displayName": "GLM-4.7",
      "baseUrl": "https://api.z.ai/api/coding/paas/v4",
      "apiKey": "${ZAI_API_KEY}",
      "provider": "generic-chat-completion-api"
    },
    {
      "model": "MiniMax-M2.1",
      "displayName": "MiniMax-M2.1",
      "baseUrl": "https://api.minimax.io/v1",
      "apiKey": "${MINIMAX_API_KEY}",
      "provider": "generic-chat-completion-api"
    }
  ]
}
Heads-up: MiniMax has since retired
MiniMax-M2.1, and its model list shows which models are current. Swap in a current id if you're setting this up today. The config shape stays the same.
Pricing
MiniMax offers competitive pay-as-you-go pricing:
- Input: ~$0.30/1M tokens
- Output: ~$1.20/1M tokens
What I use it for
A fallback when GLM-4.7 hits rate limits. I didn't benchmark this one either.
Using Droid with MiniMax M2.1
# Interactive session, then pick "MiniMax-M2.1" in /model
droid

# Generate tests
droid exec --auto low --model "custom:MiniMax-M2.1-1" "Write unit tests for the authentication module"

# Migrate code
droid exec --auto low --model "custom:MiniMax-M2.1-1" "Migrate src/services/data.js from class-based to functional"
Switching between models
One settings file, many models
You don't need separate config files. Every model in customModels shows up in Droid's model picker under Custom Models, labeled with its displayName.
Switch models
# Interactive: switch mid-session with the /model command
droid
# > /model

# One-shot: pick the model per run (the index is the entry's position in customModels, from 0)
droid exec --model "custom:GLM-4.7-0" "Help me with this bug"
droid exec --model "custom:MiniMax-M2.1-1" "Review the changes in this branch"

# No --model: Droid uses your default model (Claude, in my case)
droid exec "Plan a new feature"
Keeping keys out of the file
The only environment variables this setup needs are your provider keys. Droid expands ${ZAI_API_KEY} and ${MINIMAX_API_KEY} from the apiKey fields above when it calls each provider:
# Add to ~/.bashrc or ~/.zshrc
export ZAI_API_KEY=your-zai-key
export MINIMAX_API_KEY=your-minimax-key
Common workflows
For each of these I run the prompt on GLM-4.7 first and switch to MiniMax M2.1 when GLM-4.7 is rate-limited. Same prompt, different --model.
1. Code generation
Prompt: "Create a user authentication system with JWT"
# Generate with GLM-4.7
droid exec --auto low --model "custom:GLM-4.7-0" "Create a user authentication system with JWT using Express"

# Generate with MiniMax M2.1
droid exec --auto low --model "custom:MiniMax-M2.1-1" "Create a user authentication system with JWT using Express"
2. Code refactoring
Prompt: "Refactor this code to use async/await"
# Refactor with GLM-4.7
droid exec --auto low --model "custom:GLM-4.7-0" "Refactor src/legacy/callbacks.js to use async/await"

# Refactor with MiniMax M2.1
droid exec --auto low --model "custom:MiniMax-M2.1-1" "Refactor src/legacy/callbacks.js to use async/await"
3. Debugging
Prompt: "This API endpoint returns 500 error"
# Debug with GLM-4.7 (read-only by default)
droid exec --model "custom:GLM-4.7-0" "src/api/users.js fails with 'Error: Connection timed out'. Find the cause."

# Debug with MiniMax M2.1
droid exec --model "custom:MiniMax-M2.1-1" "src/api/users.js fails with 'Error: Connection timed out'. Find the cause."
4. Test generation
Prompt: "Write unit tests for the payment processor"
# Generate tests with GLM-4.7
droid exec --auto low --model "custom:GLM-4.7-0" "Write unit tests for src/services/payment.js"

# Generate tests with MiniMax M2.1
droid exec --auto low --model "custom:MiniMax-M2.1-1" "Write unit tests for src/services/payment.js"
Choosing the right model
I didn't measure quality, so I route by kind of work and by rate limits. Where I use each model has the short version: GLM-4.7 for everyday edits, MiniMax M2.1 as the fallback, and Claude for architecture and multi-file refactors.
Advanced configuration
Custom temperature settings
Droid passes provider-specific parameters through an extraArgs object on the model entry:
{
  "model": "glm-4.7",
  "displayName": "GLM-4.7",
  "baseUrl": "https://api.z.ai/api/coding/paas/v4",
  "apiKey": "${ZAI_API_KEY}",
  "provider": "generic-chat-completion-api",
  "extraArgs": {
    "temperature": 0.3
  }
}
- 0.0-0.2: More deterministic, good for refactoring
- 0.3-0.5: Balanced, good for feature development
- 0.6-0.8: More creative, good for brainstorming
- 0.9-1.0: Very creative, good for ideation
Output and context limits
For large codebases, cap replies with maxOutputTokens:
{
  "model": "glm-4.7",
  "displayName": "GLM-4.7",
  "baseUrl": "https://api.z.ai/api/coding/paas/v4",
  "apiKey": "${ZAI_API_KEY}",
  "provider": "generic-chat-completion-api",
  "maxOutputTokens": 32000
}
You can also add maxContextLimit with the context window your provider documents for the model. Droid compacts the conversation to stay inside it.
Troubleshooting
API key issues
Problem: "Invalid API key" error
Solution:
# Check the apiKey reference in your settings
cat ~/.factory/settings.json

# Check the environment variable it points to
echo $ZAI_API_KEY

# Regenerate key if needed
Also confirm the baseUrl matches your provider's docs. For Z.ai, a Coding Plan key bills against your plan; a standard API key doesn't.
Model not found
Problem: "Model not supported" error, or the model doesn't show up in /model
Solution:
# Verify model name matches the provider's id exactly
# GLM-4.7: "glm-4.7"
# MiniMax M2.1: "MiniMax-M2.1"
If a model is missing from the picker, check the JSON syntax in ~/.factory/settings.json and that every required field is there. provider must be exactly anthropic, openai, generic-chat-completion-api or bedrock-converse.
Rate limiting
Problem: Too many requests
Solution:
# Use different model for the next run
droid exec --model "custom:MiniMax-M2.1-1" "Continue fixing the failing tests"

# Or switch inside an interactive session
# > /model
Each provider sets its own rate limits, so check your quota in the Z.ai or MiniMax dashboard.
Connection issues
Problem: Can't connect to API
Solution:
# Check base URL
# GLM-4.7: https://api.z.ai/api/coding/paas/v4
# MiniMax: https://api.minimax.io/v1
Best practices
1. Use aliases for quick switching
# Add to ~/.bashrc or ~/.zshrc
alias droid-glm='droid exec --model "custom:GLM-4.7-0"'
alias droid-mm='droid exec --model "custom:MiniMax-M2.1-1"'
alias droid-claude='droid exec'

# Usage (add --auto low when you want it to edit files)
droid-glm --auto low "Create a new feature"
droid-mm "Debug this issue"
droid-claude "Plan this architecture"
2. Save common prompts
Create a prompts file:
# prompts.txt
Create a REST API with authentication
Generate unit tests for all files in src/
Refactor to use TypeScript
Add error handling to all API endpoints
Use them:
droid "$(cat prompts.txt | grep "API")"
3. Monitor token usage
# In an interactive session, /cost shows the cost breakdown
# > /cost

# For GLM-4.7, track Coding Plan usage at z.ai dashboard
# For MiniMax, track pay-as-you-go usage at platform.minimax.io
4. Version control generated code
# Always review before committing
droid-glm --auto low "Add user profile feature"
git diff

# Commit with model info
git commit -m "feat: user profile (GLM-4.7)"
5. Test generated code
# Run linter
npm run lint

# Run tests
npm test

# Manual verification
npm start
Where I use each model
I didn't benchmark these models, so this is how I route work, not a quality ranking:
| Work | Model |
|---|---|
| Everyday edits, CRUD, small refactors | GLM-4.7 |
| Fallback when GLM-4.7 hits rate limits | MiniMax M2.1 |
| Architecture and multi-file refactors | Claude |
My current setup
After experimenting for a while, here's what I settled on:
- GLM-4.7 ($3/month): My daily driver for everyday coding tasks
- Claude Pro ($20/month): Reserved for complex architecture decisions and multi-file refactoring
- MiniMax M2.1 (pay-as-you-go): Backup when either hits rate limits
Total monthly cost: ~$25 for AI coding across three providers.
Multi-model routing trade-offs
The lesson I keep coming back to: pinning your whole development workflow to a single commercial model is a liability. Rate limits, sudden price changes and API degradation happen without notice.
Routing routine tasks to cheaper models and keeping Claude for architecture work costs me about $5 a month more than Claude Pro alone, and gives me a fallback when one provider rate-limits me. I still review every diff myself.
Resources
Frequently asked questions
- How much does GLM-4.7 cost compared to Claude Pro for AI coding?
- GLM-4.7 on the Z.ai Coding Plan costs $3/month versus $20/month for Claude Pro, about 85% less. Per token it works out to roughly $0.48 per 1M tokens versus about $9.00 for Claude 3.5 Sonnet.
- What is Factory Droid?
- Droid is Factory's AI coding agent CLI. It works with any LLM provider that exposes an OpenAI-compatible API, so you can point it at GLM-4.7 or MiniMax M2.1 and keep Claude for complex planning.
Related posts
- 9Router: one local endpoint in front of every AI coding account I have
9Router puts 6 Antigravity, 2 Codex Pro, Claude Max and other accounts behind one localhost endpoint. Fallback, round robin and fusion combos hide rate limits.
- Build an n8n workflow that summarizes Hacker News with an LLM
A 7-node n8n workflow that pulls the top Hacker News stories, sends them to an LLM and returns a short digest. Runs locally in Docker with no paid API.
- opencode-9router: model discovery for OpenCode from a 9Router gateway
An OpenCode plugin that asks a 9Router gateway for its models at startup, fills in limits and capabilities, and caches the list. v1.0.0, 26 tests after a six-fix PR.