- Published on
Build an n8n workflow that summarizes Hacker News with an LLM
- Authors

- Name
- Nadim Tuhin
- @nadimtuhin
On this page
Most "automate it with AI" demos stop at a screenshot. This one's a workflow you can import, run and change in about ten minutes.
I use small workflows like this for clients who want a daily digest of something (news, tickets, competitor pages) without another SaaS subscription. The pattern never changes: fetch, shape, ask an LLM, deliver.
What we're building
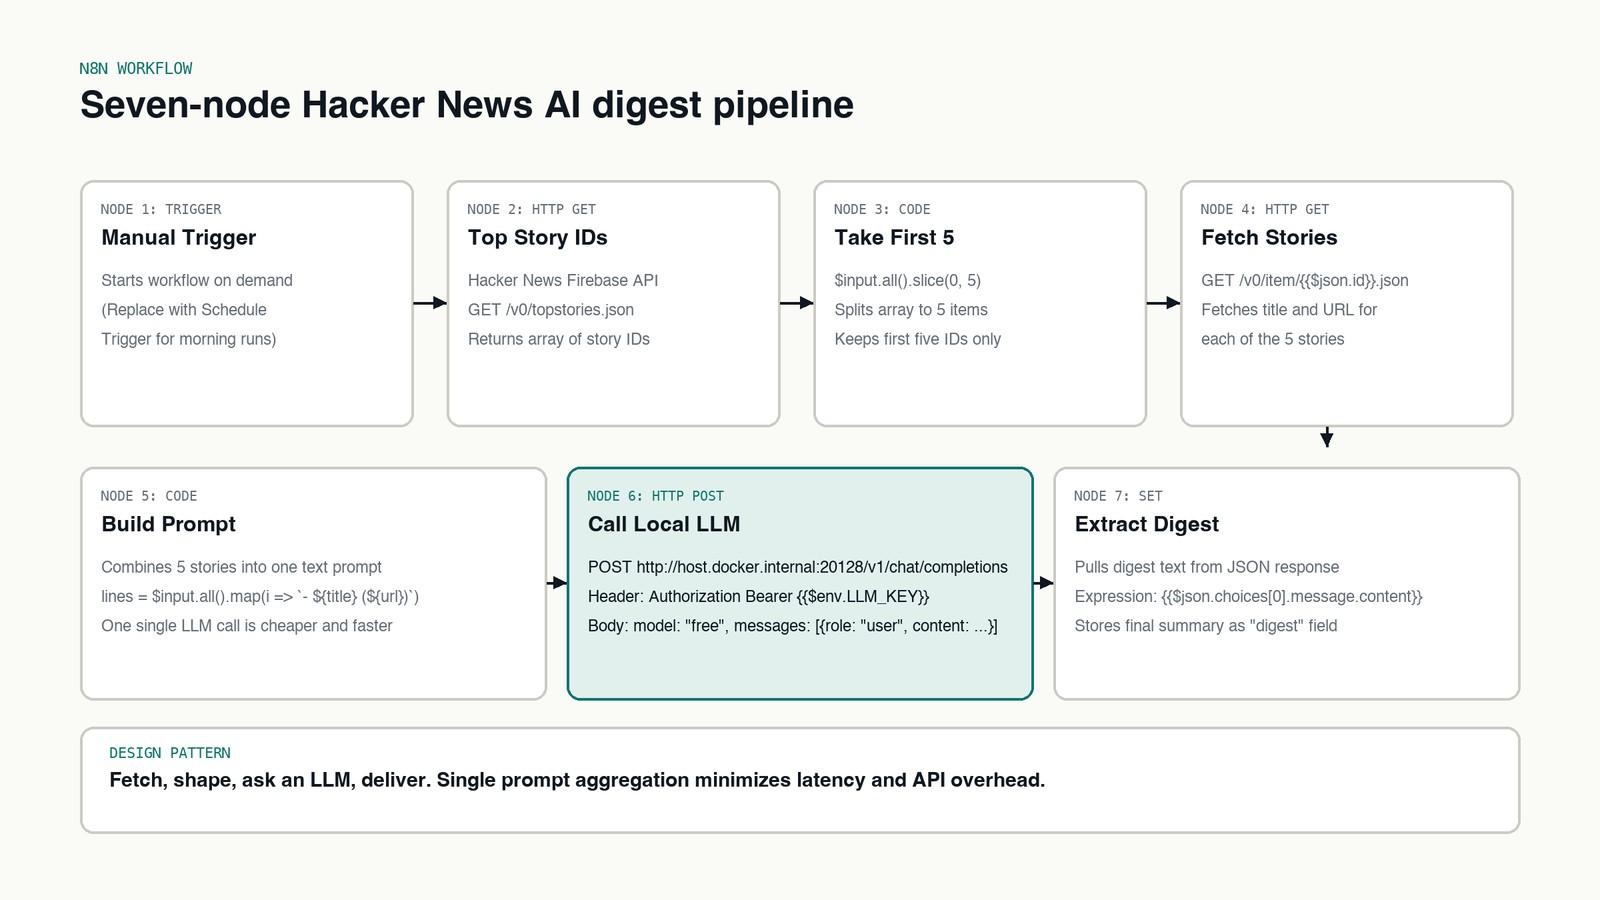
A manual-trigger workflow with 7 nodes that:
- Fetches the top story ids from the Hacker News API
- Keeps the first 5
- Fetches each story
- Builds one prompt from the titles and links
- Sends it to an LLM
- Returns a digest plus the single most useful story for a developer
Real output from my last run:
Magnitude provides self-optimizing inference engine for agents.
Commit Description demonstrates using commit messages as thinking tool.
Bloomberg terminal history covers evolution of financial data terminals.
You Said No MCP discusses Model Context Protocol.
I Could've Accessed 17T Microsoft Records describes security researcher access to massive data.
Most useful: Commit Description as a Thinking Tool.
Run it locally
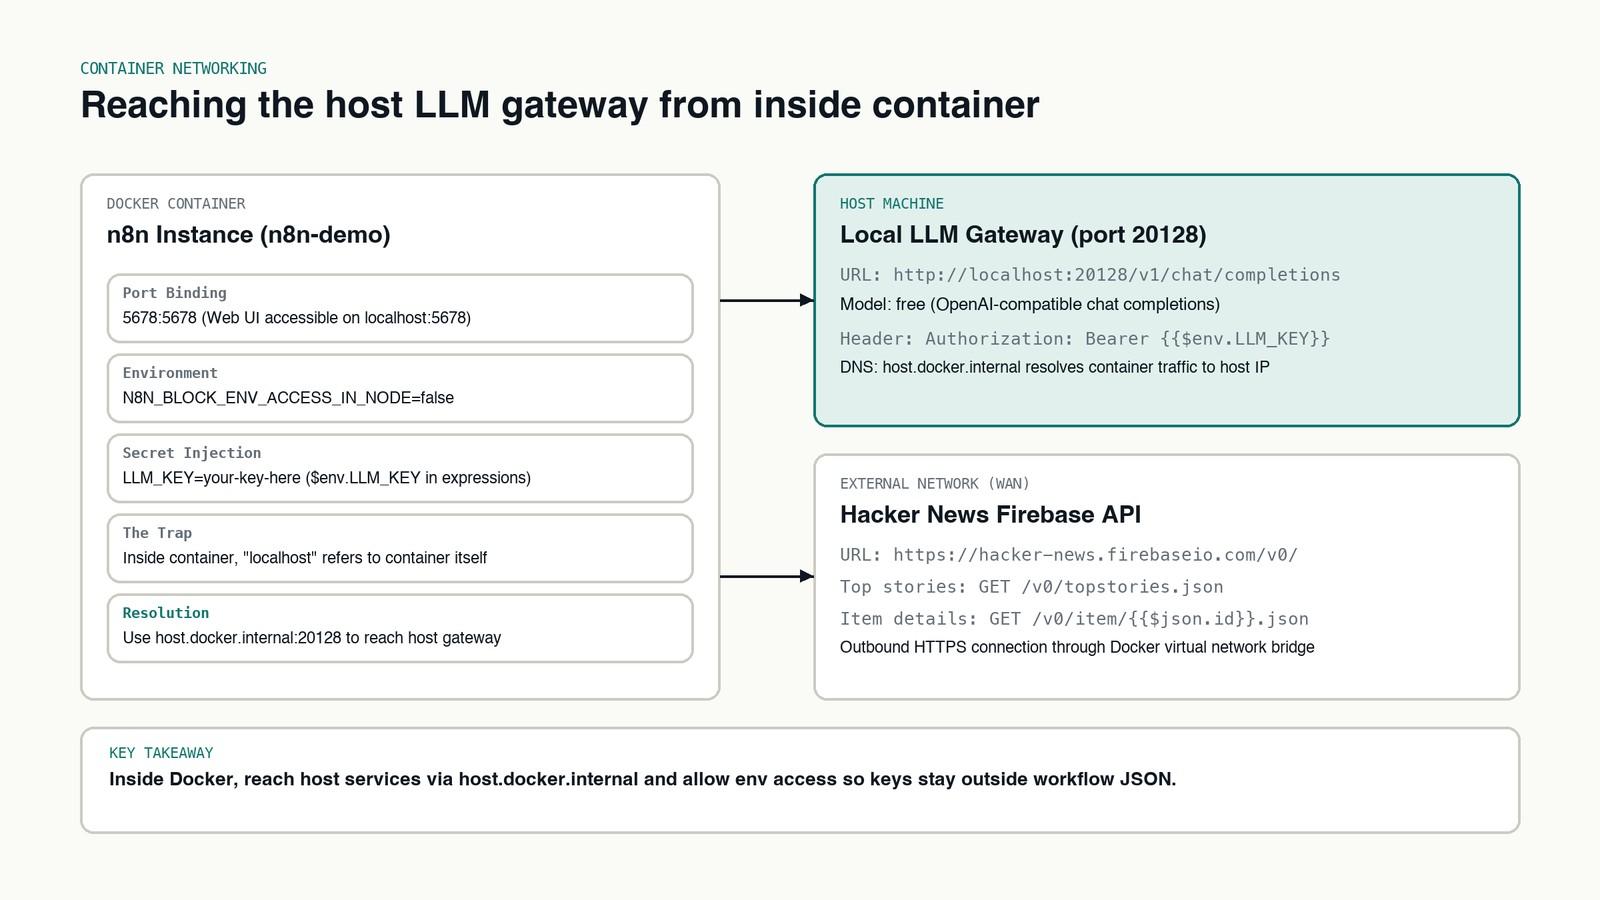
You need two things: Docker and an OpenAI-compatible HTTP service. I run a local model gateway at http://localhost:20128/v1, which keeps it free. Any provider that exposes /chat/completions works too, with no config changes.
Start the n8n container so it can read environment variables:
docker run -d --name n8n-demo -p 5678:5678 \
  -e N8N_BLOCK_ENV_ACCESS_IN_NODE=false \
  -e LLM_KEY=your-key-here \
  -v n8n-data:/home/node/.n8n \
  n8nio/n8n:latest
N8N_BLOCK_ENV_ACCESS_IN_NODE=false lets expressions read $env.LLM_KEY at runtime. That way the secret stays in the container environment instead of landing in exported workflow files. Then open http://localhost:5678 to set up the instance.
Fetch only what you need
The pipeline talks to Hacker News through two HTTP Request nodes:
- Top story IDs:
GET https://hacker-news.firebaseio.com/v0/topstories.json - Item detail:
GET https://hacker-news.firebaseio.com/v0/item/{{ $json.id }}.json
The top stories endpoint returns hundreds of story IDs. Fetch the details for all of them in parallel and you fire hundreds of concurrent requests, which hits API rate limits and adds latency.
So a Code node trims the list to the batch size before any detail requests go out.
One quirk to know: n8n splits a JSON array response into separate items, and a bare integer arrives wrapped as json.data. The code keeps the first five and normalizes the shape:
// Code node: "Take first 5"
return $input
  .all()
  .slice(0, 5)
  .map((i) => ({ json: { id: i.json.data ?? i.json } }))
One prompt, one model call
A separate request per story multiplies inference cost and adds needless round trips. Packing all five into one prompt gets every summary from a single model call.
A Code node gathers the items with $input.all(), puts no url in place of any missing link, and builds the prompt string:
// Code node: "Build prompt"
const lines = $input.all().map((i) => `- ${i.json.title} (${i.json.url || 'no url'})`)
return [
  {
    json: {
      prompt:
        'Summarize these Hacker News stories in one sentence each, then name the single most useful one for a developer:\n' +
        lines.join('\n'),
    },
  },
]
Calling the LLM
An HTTP Request node sends the prompt with POST to http://host.docker.internal:20128/v1/chat/completions.
Why not localhost? Inside the container, localhost means the container itself. host.docker.internal routes the request back to the host, where the model gateway is listening.
- Header:
Authorization: Bearer {{ $env.LLM_KEY }} - Body (JSON):
={{ JSON.stringify({ model: 'free', messages: [{ role: 'user', content: $json.prompt }] }) }}
A Set node pulls {{ $json.choices[0].message.content }} into a digest field. From there you can send it anywhere: a Slack channel, a Discord bot or an internal event bus.
Running it from the CLI
Handy when you want to test without clicking through the editor:
docker exec n8n-demo n8n import:workflow --input=/tmp/hn-digest.json
docker exec -e N8N_RUNNERS_BROKER_PORT=5690 n8n-demo n8n execute --id=hndigest0000001
Two traps that cost me time:
import:workflowfails withNOT NULL constraint failed: workflow_entity.idunless the JSON has a top-level"id".n8n executeinside a running container collides on the task broker port (5679). SettingN8N_RUNNERS_BROKER_PORTto another port fixes it.
When to use this, and when not to
Good fit:
- A daily or weekly digest for a small team
- Any "read a list, summarize, send somewhere" job
- Prototyping before you commit to custom code
Not a good fit:
- Anything that needs exact, auditable output. LLM summaries vary between runs.
- Heavy scraping of sites that block bots. Use a real browser automation setup for that.
What's next
Swap the manual trigger for a Schedule Trigger and add a Slack, email or Telegram node at the end. Now the demo is something your team reads every morning.
Keeping automations minimal
The whole thing is seven nodes and two short scripts. The hard part is rarely the workflow. It's deciding which manual task is worth automating, and what a good result looks like.
If you have a process like that, book a 30 minute call and tell me what you want to stop doing by hand.
Resources
Frequently asked questions
- Can n8n call a local LLM?
- Yes. The HTTP Request node can POST to any OpenAI-compatible endpoint, including a local gateway. From inside Docker, reach the host with host.docker.internal.
- Why does the Code node get one item per id instead of an array?
- The HTTP Request node splits a JSON array response into one n8n item per element. Read them with $input.all() instead of indexing into a single array.
Related posts
- ytranscript: YouTube transcripts into Obsidian, n8n and Claude
I lost a video in 400+ Watch Later items. ytranscript fetches transcripts with no API key, feeds my n8n to Obsidian flow and runs as an MCP server for Claude.
- Linting my blog for AI-sounding prose: what worked, what I skipped
I ran a free prose linter over 31 posts, made 25 edits in 13 of them and added a pre-commit check. I skipped AI detectors and humanizers.
- Hermes Agent: nightly cron jobs and skills learned from corrections
Hermes runs nightly CLI updates, a security PR scan every 6 hours and a 30-minute autoheal job. Every correction I make becomes a skill file. Hermes drafts, I send.