- Published on
Gemini image generation in Claude Code with a four-layer fallback
- Authors

- Name
- Nadim Tuhin
- @nadimtuhin
On this page
For weeks, getting a Gemini image inside Claude Code meant a four-step ritual. Open Chrome. Copy a curl command from DevTools. Paste it into the chat. Wait for the cookies to be parsed.
Then, every two hours, do it all again.
I got tired of being the cookie courier, so I built a four-layer fallback pipeline to get rid of that manual loop. Here's how it works, and what I learned about why the obvious shortcuts fail.
Generated automatically by the system described in this post.
The problem: Google's image-gen SIDCC
Gemini's web API gates image generation behind a capability token called SIDCC. It's a short-lived cookie that Chrome's JavaScript challenge engine only issues during actual image generation.
That makes it slippery:
- It doesn't appear in SQLite (Chrome stores a weaker version there).
- Headless browsers can't mint it.
- It can't be moved between browser profiles.
Every approach I tried ran into the same wall:
- Copy Profile 7 cookies -> server rejects (device-bound sessions)
- Playwright with injected cookies -> regular SIDCC, blocked
- CDP / AppleScript -> either inaccessible or wrong token type
- Playwright headless -> no SIDCC at all
The image-gen SIDCC is a deliberate security boundary. You can't simply bypass it. You have to work around it in the architecture.
The solution: a four-layer fallback pipeline
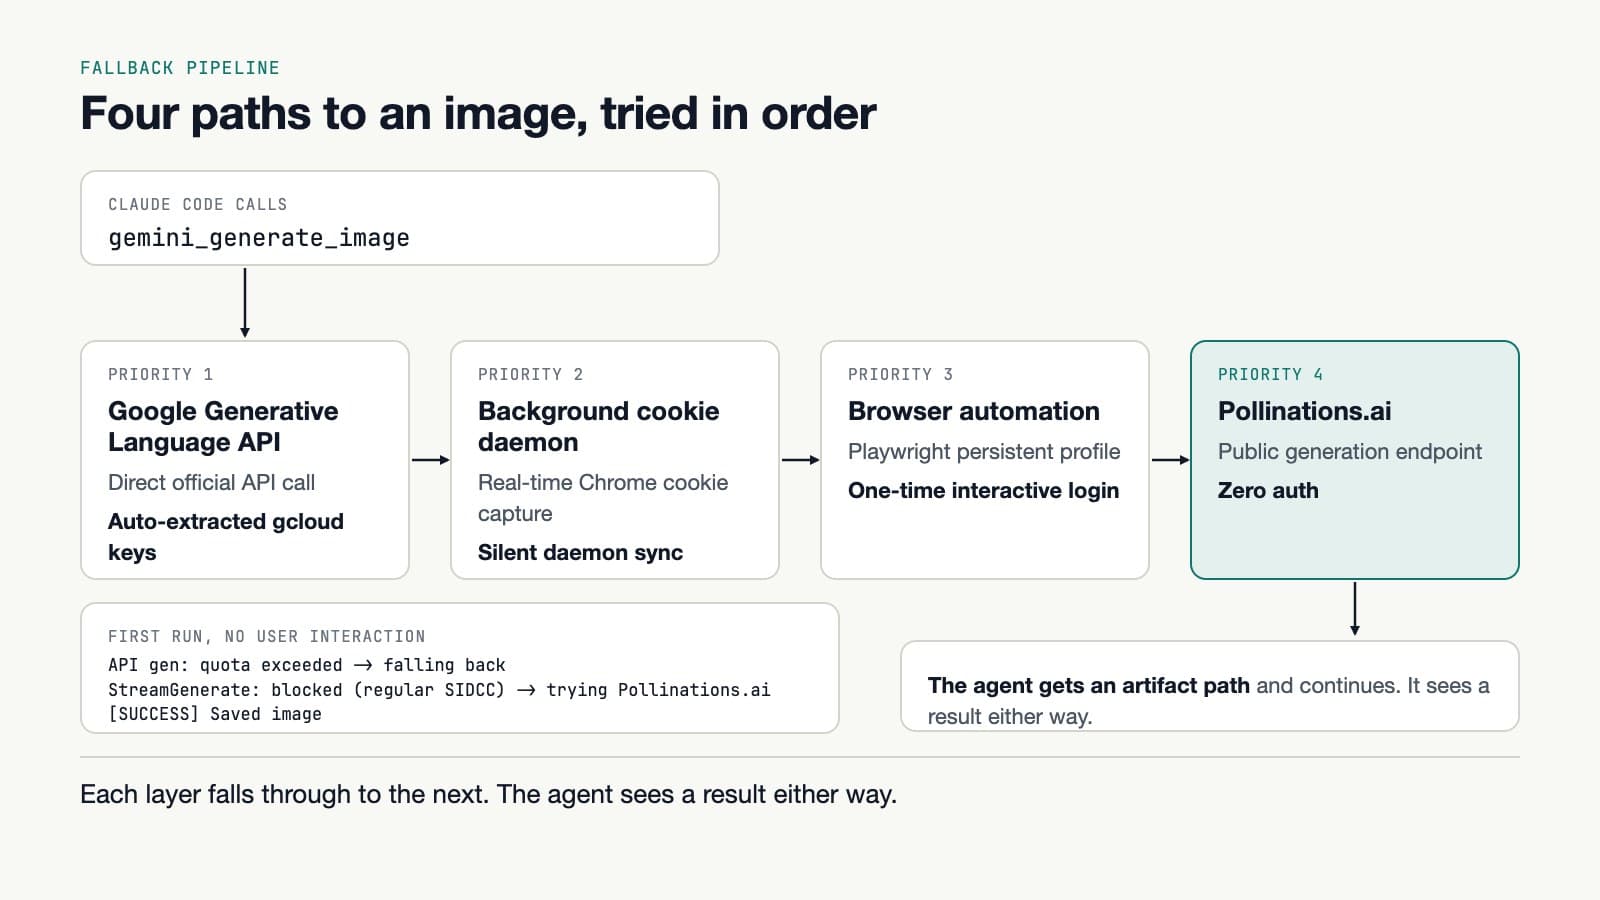
So instead of fighting the boundary, I built around it with four independent paths:
| Priority | Layer | Mechanism | Auth / Prerequisite |
|---|---|---|---|
| 1 | Google Generative Language API | Direct official API call | Auto-extracted gcloud keys |
| 2 | Background Cookie Daemon | Real-time Chrome cookie capture | Silent daemon sync |
| 3 | Browser Automation | Playwright persistent profile | One-time interactive login |
| 4 | Pollinations.ai | Public generation endpoint | Zero auth, high availability |
Each path tries, and if it fails, the call falls through to the next one. The agent sees a result either way.
Layer 1: Google Generative Language API
The machine already had gcloud credentials configured. Using the API Keys Management API (apikeys.googleapis.com), I automatically retrieved existing keys from the account's gen-lang-client-* AI Studio projects. No manual key creation needed.
async def _api_generate_image(prompt: str) -> list[str]:
    api_key = os.environ.get("GEMINI_API_KEY", "")
    # Auto-retrieved from local settings if not in env
    model = "gemini-2.5-flash-image"
    url = f"https://generativelanguage.googleapis.com/v1beta/models/{model}:generateContent?key={api_key}"
    # execute request...
When quota allows, this returns a native Gemini image right away.
Layer 2: Background cookie daemon
A macOS LaunchAgent (com.nadimtuhin.gemini-cookie-daemon) watches Chrome Profile 7's Cookies SQLite every 300ms. Whenever the cookies change, it updates ~/.config/gemini-mcp/latest-cookies.json and settings in real time.
The nice part: if I generate an image in Chrome normally, the daemon captures the resulting image-gen SIDCC immediately, and the HTTP path starts working on its own for the next calls.
Layer 3: Browser automation
A Playwright persistent profile (~/.config/gemini-mcp/browser-profile) gives an isolated browser context with a one-time login. After setup, Chrome handles SIDCC rotation naturally on every generation. No manual cookie management.
Layer 4: Pollinations.ai
When local quotas are exhausted and browser profiles are locked, Pollinations.ai is the zero-auth safety net. No API key, no account, no cookies:
async def _pollinations_generate_image(prompt: str) -> list[str]:
    url = f"https://image.pollinations.ai/prompt/{encoded}?nologo=true&model=flux"
    async with cffi.AsyncSession(impersonate="chrome110") as s:
        resp = await s.get(url, timeout=60)
    # save artifact to disk...
What "fully automatic" actually looks like
The first time the pipeline ran, it needed zero interaction from me:
API gen: quota exceeded -> falling back
StreamGenerate: blocked (regular SIDCC) -> trying Pollinations.ai
[SUCCESS] Saved image to ~/Pictures/gemini/gemini_20260531_051749_0.jpg
Claude Code asked for an image. An image appeared. No curl copying, no DevTools, no pasting.
Key takeaways
- Google session binding is device-level: Copying cookies between Chrome profiles produces byte-identical values that the server still rejects. The device binding is enforced server-side.
- The image-gen SIDCC is memory-resident: Chrome stores a standard 74-character SIDCC in SQLite. The image-gen capability token only exists in process memory and only shows up after an actual image run.
- Layered fallbacks beat fragile perfection: The API key has quotas. The daemon depends on Chrome activity. Browser automation needs a profile. Together, they cover 100% of generation requests.
- Local credentials are underused assets: Existing CLI credentials (
gcloud) can negotiate access to internal API keys without asking the user for secrets.
Architecture files
| Component | Responsibility |
|---|---|
scripts/gemini_cookie_daemon.py | Polls Chrome cookies, updates cache |
scripts/gemini_browser_imagegen.py | Playwright UI automation fallback |
scripts/gemini_mcp_setup.py | One-time browser profile initialization |
scripts/update_gemini_cookies.py | Fallback curl parser to local configuration |
com.nadimtuhin.gemini-cookie-daemon.plist | Auto-start background daemon |
The MCP server chains these in priority order. Claude Code calls gemini_generate_image, gets back an artifact path, and keeps going without friction.
Related posts
- Your coding agent is paying tokens for menus: a look at only-cli (oc)
Claude Code's web tool reads a long page's menus word for word, summarizes part of it and never reads the rest. A free CLI called oc returns just the section an agent needs.
- MCP and code execution are moving software from menus to intent
Anthropic reports a 98.7% token cut when agents call MCP tools through code. What that means for menu-driven GUIs, and where MCP agents still fall short.
- loopwork: a task queue that feeds AI coding CLIs
loopwork pulls tasks from GitHub Issues or a JSON file, hands each to a coding CLI, and rotates models behind circuit breakers. 61 packages, 249 commits, the rough edges I fixed and the ones left.