- Published on
ytranscript: YouTube transcripts into Obsidian, n8n and Claude
- Authors

- Name
- Nadim Tuhin
- @nadimtuhin
On this page
Last week I spent 20 minutes hunting for a video I'd watched months ago. Something about API rate limiting patterns.
I knew the exact moment: the speaker drew a diagram on a whiteboard that made everything click. But I couldn't find it. My Watch Later had 400+ videos, and my bookmarks were useless.
That diagram is gone. I'll probably never find it.
This keeps happening. So I'm building a system to fix it.
The core insight
Once you have transcripts, everything becomes searchable. The video I lost? With the transcript, I could grep for "rate limit" and find it in seconds. I could feed it to an LLM for a summary, or link it to my notes on API design.
The output format doesn't matter yet: blog posts, mindmaps, a searchable wiki, whatever. The bottleneck is getting text out of videos and into my note system automatically.
My current workflow
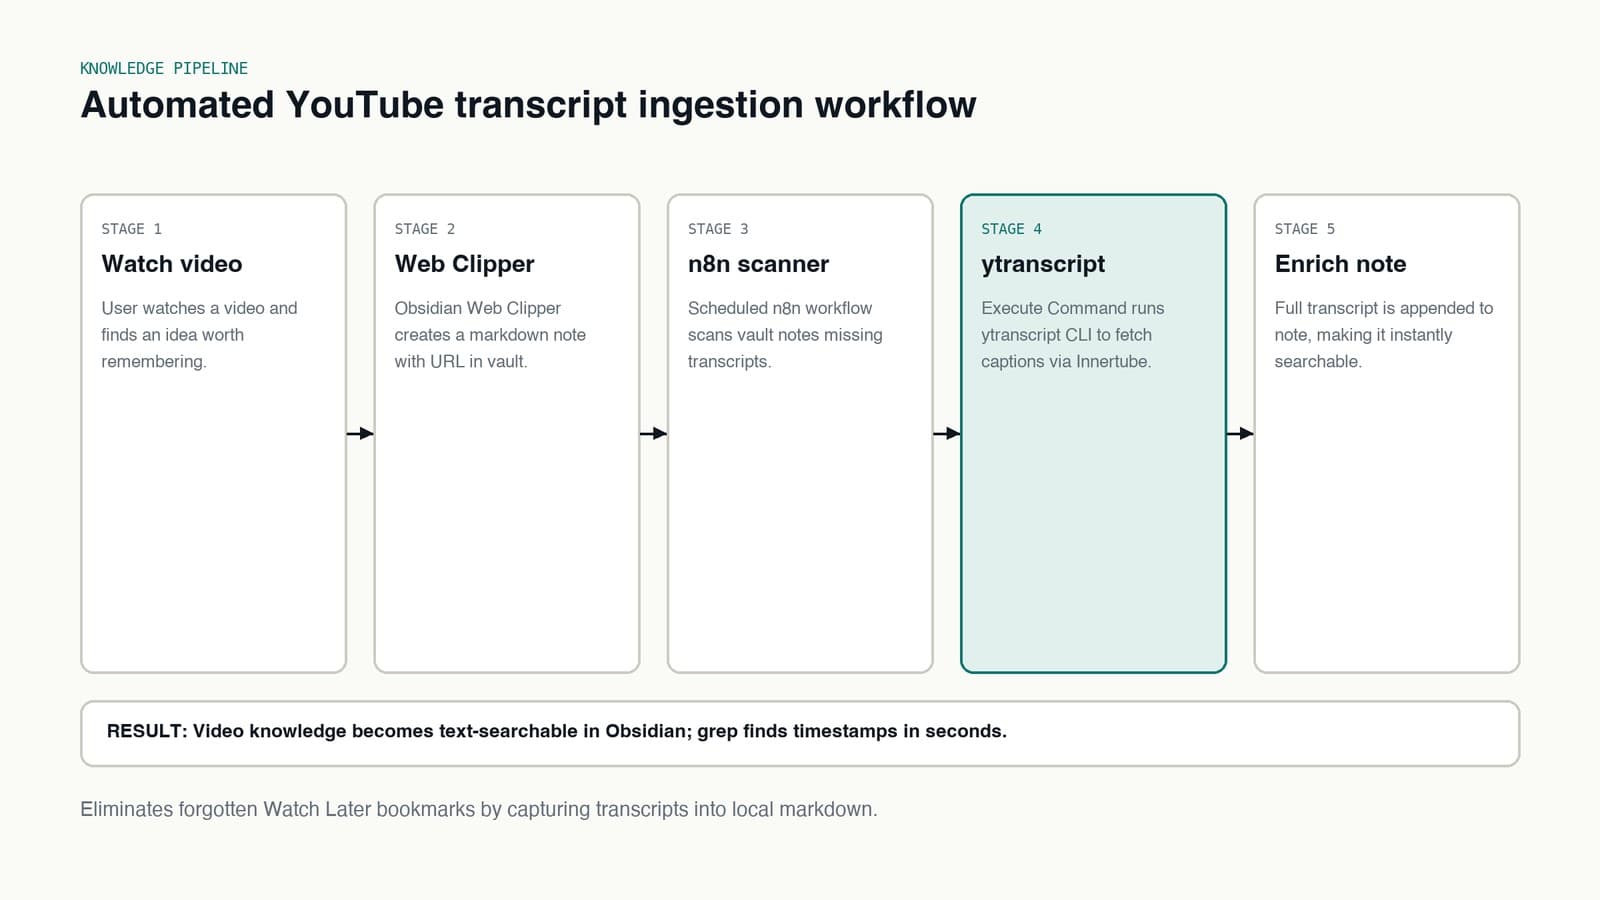
1
Find something worth remembering
2
Clip with Obsidian Web Clipper
Creates a note with the URL in my vault
3
Scans vault for notes with YouTube URLs missing transcripts
4
ytranscript fetches the transcript
CLI call from n8n's Execute Command node
5
Full transcript appended, now searchable
n8n is an open-source workflow automation tool. Think Zapier, but self-hosted. Obsidian Web Clipper saves web pages to your vault with one click.
Why I built ytranscript
I tried the existing options first:
- Third-party APIs (youtubetotranscript.com, etc.): they work until they don't. Rate limits, downtime, sometimes paid.
- Python's youtube-transcript-api: a good library, but I wanted something I could call from n8n without setting up a Python environment.
- Browser extensions: manual. The whole point is automation.
What I needed was a CLI I could call from a shell script or an n8n node. Minimal setup, no API keys, no accounts.
So I built ytranscript. It talks to YouTube's internal Innertube API directly, the same one their web player uses.
Note: This tool uses an undocumented YouTube API that could change at any time. Not all videos have transcripts available (age-restricted, private, or videos without captions).
Usage
# Install globally
npm install -g @nadimtuhin/ytranscript

# Fetch a transcript
ytranscript get "https://youtube.com/watch?v=dQw4w9WgXcQ"

# Or run without installing (npx)
npx @nadimtuhin/ytranscript get VIDEO_ID

# Check available languages
ytranscript info VIDEO_ID

# Output as SRT subtitles
ytranscript get VIDEO_ID --format srt -o captions.srt
In n8n, use the Execute Command node:
npx @nadimtuhin/ytranscript get "{{ $json.youtube_url }}" --format text
For bulk processing (e.g., your entire Watch Later export from Google Takeout):
ytranscript bulk --file video-ids.txt --out-jsonl transcripts.jsonl --resume
The --resume flag skips videos it's already done. Handy, because I had a backlog of 200+ to get through.
Rate limiting: YouTube will throttle aggressive requests. Use
--pause-after 10 --pause-ms 5000for large batches to avoid getting blocked.
MCP integration
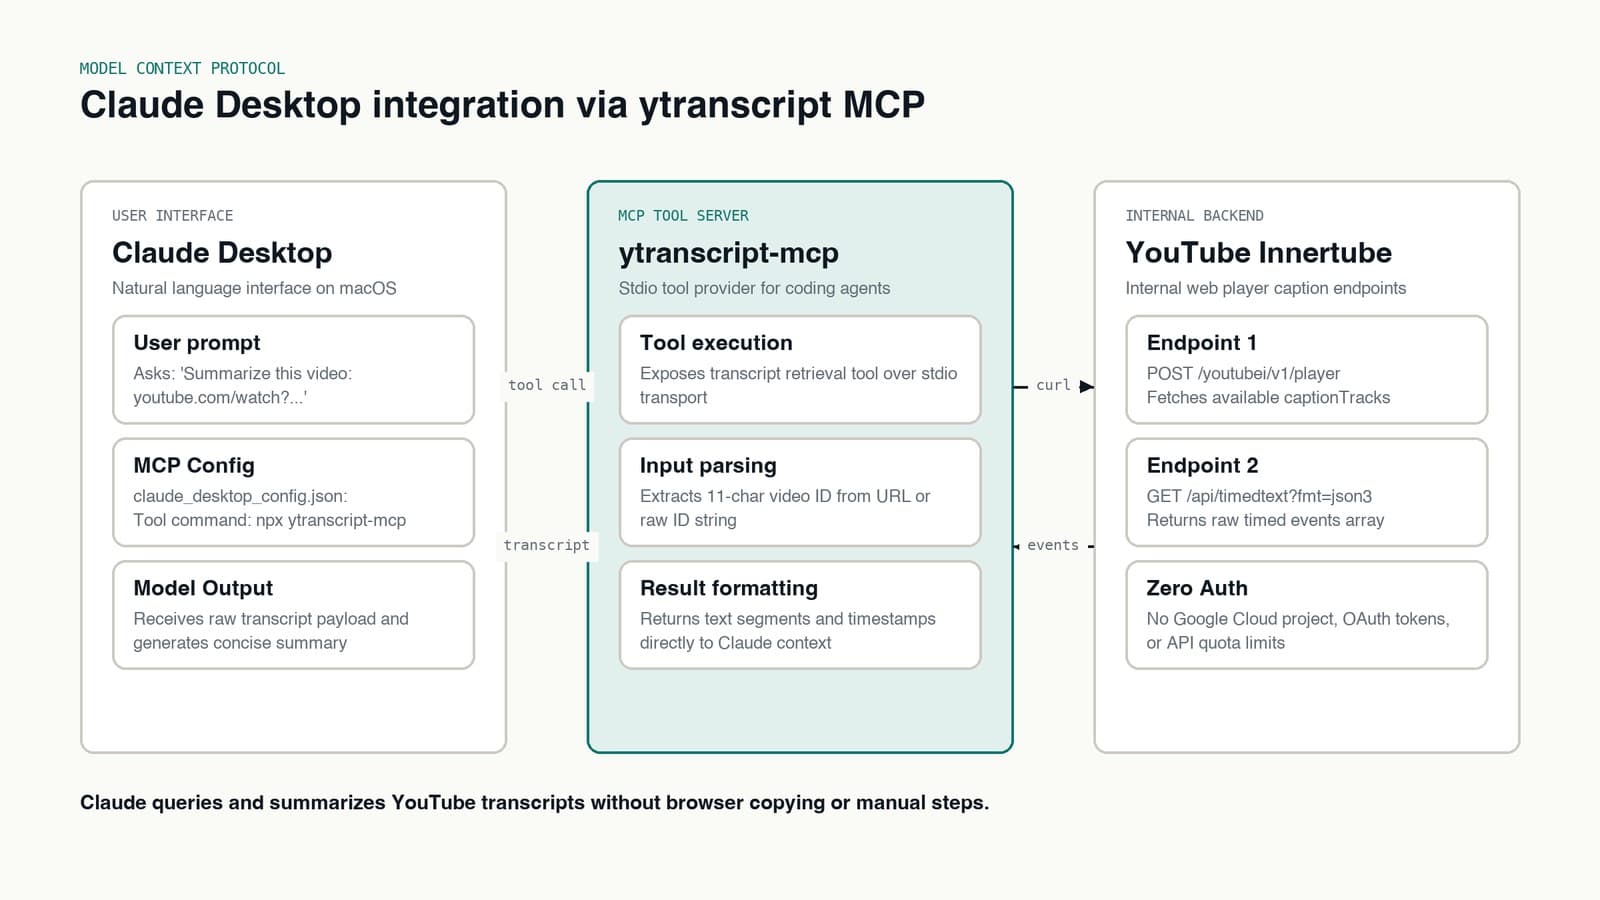
I also added an MCP server, so Claude can fetch transcripts directly. Add this to your Claude Desktop config (~/Library/Application Support/Claude/claude_desktop_config.json on macOS):
{
  "mcpServers": {
    "ytranscript": {
      "command": "npx",
      "args": ["-y", "ytranscript-mcp"]
    }
  }
}
Or if you have it installed globally:
{
  "mcpServers": {
    "ytranscript": {
      "command": "ytranscript-mcp"
    }
  }
}
Now Claude can handle "summarize this YouTube video" without you copy-pasting anything.
What I haven't figured out yet
The transcript fetching works. What I'm still experimenting with:
- Summarization: should the n8n workflow call an LLM to write a TL;DR? Or do I summarize on demand when I revisit a note?
- Tagging: auto-extract topics and link them to existing notes in my vault?
- Format: a plain text dump, or structured with timestamps so I can jump back to specific moments?
I'll write a follow-up once I've settled on something.
Links
It's open source. If you're building something similar, I'd love to see what your pipeline looks like.
Related posts
- Build an n8n workflow that summarizes Hacker News with an LLM
A 7-node n8n workflow that pulls the top Hacker News stories, sends them to an LLM and returns a short digest. Runs locally in Docker with no paid API.
- loopwork: a task queue that feeds AI coding CLIs
loopwork pulls tasks from GitHub Issues or a JSON file, hands each to a coding CLI, and rotates models behind circuit breakers. 61 packages, 249 commits, the rough edges I fixed and the ones left.
- How ytranscript works: reverse-engineering YouTube captions
How ytranscript pulls YouTube captions using the internal Innertube API: no browser, no API keys, just curl and a simple JSON parser.