- Published on
How ytranscript works: reverse-engineering YouTube captions
- Authors

- Name
- Nadim Tuhin
- @nadimtuhin
On this page
In my previous post, I introduced ytranscript, a tool I built to fetch YouTube transcripts for my knowledge pipeline. This time, let's open it up and see how it actually works.
The short version: no third-party services, no API keys. Just YouTube's own internal API.
Important caveats
Before we dig in, some honest disclaimers.
This uses an undocumented API. YouTube's Innertube API is internal and can change without notice. I've seen YouTube break similar tools before by changing endpoints, requiring authentication, or adding bot detection. If ytranscript stops working, that's why.
Terms of service. Accessing undocumented APIs may violate YouTube's ToS. This tool is for personal use, research, and educational purposes. Use it responsibly.
Known limitations:
- Age-restricted videos require authentication cookies (not supported)
- Private/unlisted videos require authentication
- Region-blocked content may fail based on your IP
- Heavy usage can get your IP rate-limited (HTTP 429) or blocked
- Auto-translation tracks are not currently supported
With that out of the way, let's look under the hood.
The Innertube API
YouTube's web player uses an internal API called Innertube to fetch video data. It's the same API that powers youtube.com. It just isn't publicly documented.
The key endpoint:
POST https://www.youtube.com/youtubei/v1/player
This returns video metadata, including the available caption tracks and their URLs.
The two-step process
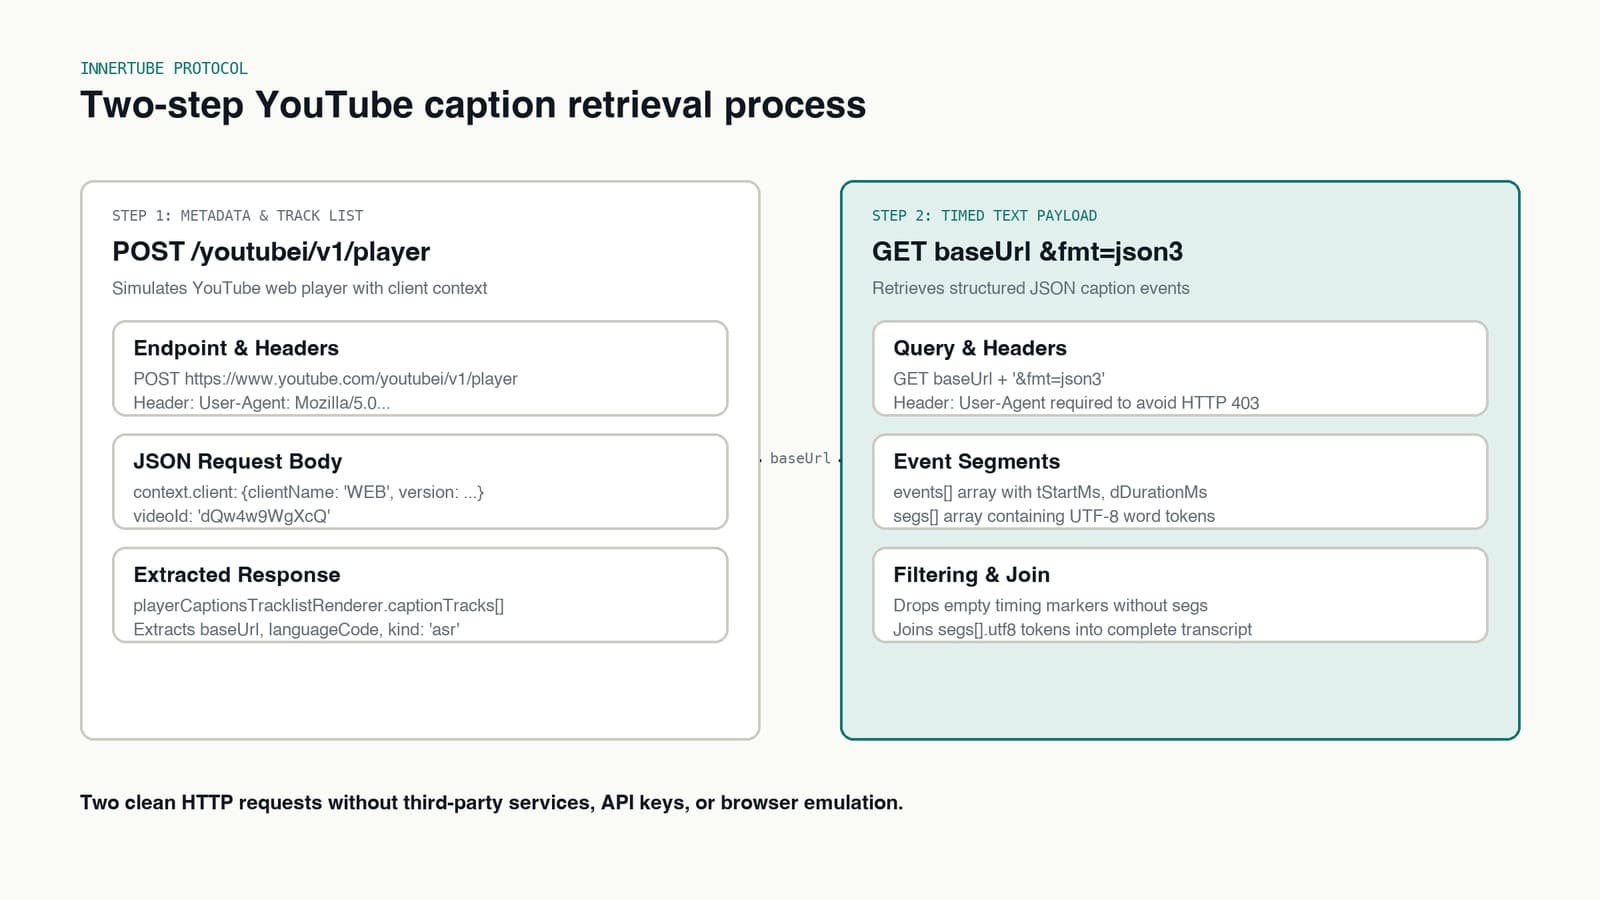
Getting a transcript takes two API calls.
Step 1: get caption track URLs
curl -X POST 'https://www.youtube.com/youtubei/v1/player?prettyPrint=false' \
  -H 'Content-Type: application/json' \
  -H 'User-Agent: Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36' \
  -d '{
    "context": {
      "client": {
        "clientName": "WEB",
        "clientVersion": "2.20240101.00.00"
      }
    },
    "videoId": "dQw4w9WgXcQ"
  }'
The response includes a captions object:
{
  "captions": {
    "playerCaptionsTracklistRenderer": {
      "captionTracks": [
        {
          "baseUrl": "https://www.youtube.com/api/timedtext?...",
          "languageCode": "en",
          "kind": "asr",
          "name": { "simpleText": "English (auto-generated)" }
        }
      ]
    }
  }
}
The fields that matter:
baseUrl: the URL to fetch the actual caption contentlanguageCode: the language code (en, es, fr, etc.)kind: "asr": marks auto-generated captions (manual captions don't have this field)
Step 2: fetch the caption track
Take the baseUrl from step 1 and append &fmt=json3 to get structured JSON. You need the User-Agent header here too:
curl -H 'User-Agent: Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36' \
  "https://www.youtube.com/api/timedtext?...&fmt=json3"
Response:
{
  "events": [
    {
      "tStartMs": 0,
      "dDurationMs": 5000,
      "segs": [{ "utf8": "Hello " }, { "utf8": "world" }]
    },
    {
      "tStartMs": 5000,
      "dDurationMs": 3000,
      "segs": [{ "utf8": "Welcome to the video" }]
    }
  ]
}
Each event has:
tStartMs: start time in millisecondsdDurationMs: duration in millisecondssegs: an array of text segments (UTF-8 encoded)
One gotcha: some events don't have segs (they're timing markers or style events), so those get filtered out.
The whole thing with jq
Here's a complete script that fetches a transcript, with error handling:
VIDEO_ID="dQw4w9WgXcQ"

# Get caption URL (returns empty if no captions)
CAPTION_URL=$(curl -s -X POST \
  'https://www.youtube.com/youtubei/v1/player?prettyPrint=false' \
  -H 'Content-Type: application/json' \
  -H 'User-Agent: Mozilla/5.0' \
  -d "{\"context\":{\"client\":{\"clientName\":\"WEB\",\"clientVersion\":\"2.20240101.00.00\"}},\"videoId\":\"$VIDEO_ID\"}" \
  | jq -r '.captions.playerCaptionsTracklistRenderer.captionTracks[0].baseUrl // empty')

if [ -n "$CAPTION_URL" ]; then
  curl -s -H 'User-Agent: Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36' \
    "$CAPTION_URL&fmt=json3" \
    | jq -r '.events[] | select(.segs) | [.segs[].utf8] | join("")'
else
  echo "No captions available"
fi
Why it won't work in browsers
If you're thinking "I'll just call this from my frontend," you can't. YouTube's API doesn't send CORS headers:
Access-Control-Allow-Origin: (missing)
So the browser blocks the request before it completes.
Workarounds
1. Proxy through your backend
import express from 'express'
import { fetchTranscript } from '@nadimtuhin/ytranscript'

const app = express()

// Validate video ID format (11 chars, alphanumeric + dash/underscore)
const isValidVideoId = (id: string) => /^[a-zA-Z0-9_-]{11}$/.test(id)

app.get('/api/transcript/:videoId', async (req, res) => {
  const { videoId } = req.params

  if (!isValidVideoId(videoId)) {
    return res.status(400).json({ error: 'Invalid video ID' })
  }

  try {
    const transcript = await fetchTranscript(videoId)
    res.json(transcript)
  } catch (error) {
    const message = error instanceof Error ? error.message : 'Unknown error'
    // Map errors to appropriate status codes
    const status = message.includes('No captions') ? 404 : 500
    res.status(status).json({ error: message })
  }
})

app.listen(3000)
2. Serverless function. Deploy on Vercel, Netlify, or AWS Lambda.
3. Browser extension. Content scripts can make same-origin requests when injected into youtube.com.
4. Just use the CLI. For automation, keep it server-side:
ytranscript get VIDEO_ID --format json
The actual return type
The real fetchTranscript function returns a Transcript object:
interface Transcript {
  videoId: string
  text: string // Full transcript as single string
  segments: Array<{
    // Individual caption segments
    text: string
    start: number // Seconds (converted from milliseconds)
    duration: number // Seconds
  }>
  language: string // e.g., "en"
  isAutoGenerated: boolean
}
The full implementation in fetcher.ts adds language selection, timeout handling, and output formatting.
How it picks a language
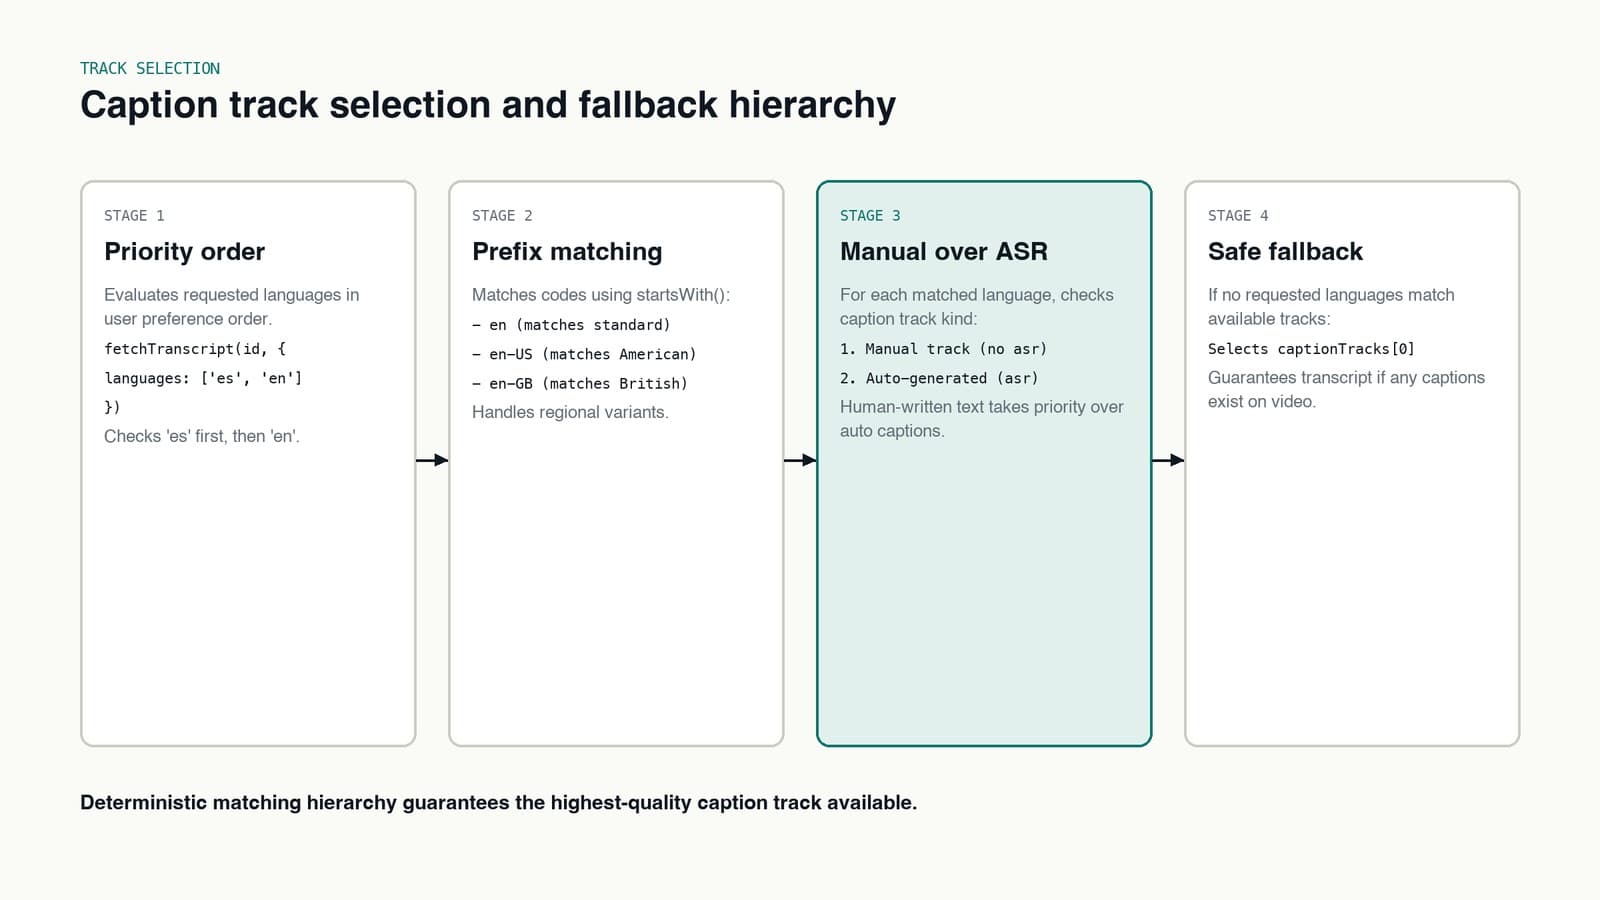
ytranscript chooses a caption track like this:
- Check each preferred language in order
- For each language, prefer manual captions over auto-generated ones
- If nothing matches, fall back to the first available track
// Prefer Spanish, fall back to English
fetchTranscript('VIDEO_ID', { languages: ['es', 'en'] })
Language codes use prefix matching via startsWith(), so en matches en, en-US, en-GB, and so on.
Rate limiting
YouTube will rate-limit aggressive requests. ytranscript has built-in throttling for bulk operations:
ytranscript bulk \
  --file videos.txt \
  --concurrency 4 \
  --pause-after 10 \
  --pause-ms 5000
This fetches 4 videos in parallel and pauses for 5 seconds after every 10 requests.
If you get HTTP 429 errors, back off hard: wait 30-60 seconds, then use exponential backoff. Keep hammering and your IP can get blocked for hours or days.
Lessons from building it
A few quirks I ran into along the way:
- User-Agent is required. YouTube rejects requests without a browser-like User-Agent.
- Client version matters (for now). The version string doesn't need to be current, but YouTube could start enforcing it.
- JSON3 format. The
fmt=json3parameter returns structured JSON. Without it, you get XML. - It will break eventually. This is an undocumented API. When YouTube changes it, the library needs updating.
Links
- GitHub: github.com/nadimtuhin/ytranscript
- npm: @nadimtuhin/ytranscript
- Technical docs: HOW_IT_WORKS.md
Sometimes the best API is the one that was never meant to be public. Just don't be surprised when it disappears.
Related posts
- opencode-9router: model discovery for OpenCode from a 9Router gateway
An OpenCode plugin that asks a 9Router gateway for its models at startup, fills in limits and capabilities, and caches the list. v1.0.0, 26 tests after a six-fix PR.
- express-simple-proxy: an Express proxy with hooks and typed errors
express-simple-proxy forwards Express routes to an upstream API with error codes, a beforeRequest hook and an onResponse callback. 183 tests, two runtime dependencies, and rough edges I found.
- devutils: 33 browser-only dev tools and what the README overstated
devutils runs JSON, JWT, SQL and Base64 tools in the browser with no network calls. I checked the README against the code: the privacy claim holds, the 35+ tool count did not.