- Authors

- Name
- Nadim Tuhin
- @nadimtuhin
On this page
Your Puppeteer script worked yesterday. Today a class name rotated and it's dead.
That's the life of hardcoded selectors. Class names rotate in build pipelines, DOM hierarchies shift, and shadow DOM boundaries hide elements. Keeping locators alive across frequent frontend releases turns into endless patch work.
AI browser agents swap rigid locator chains for goal-driven loops. Instead of hardcoding every DOM traversal, you hand over a high-level task. The agent looks at the page, picks browser actions, and adapts when the UI shifts.
Framework tradeoffs
| Framework | Best for | Language | Complexity |
|---|---|---|---|
| LangChain + LangGraph | Custom agent loops, full control | JS/TS, Python | Medium |
| Browser Use | High-volume scraping, stealth runtimes | Python, TS | Low |
| Stagehand | Hybrid code with self-healing locators | JS/TS | Low |
| Skyvern | Multi-page enterprise workflows | Python | Medium |
In this guide I'll use LangChain + LangGraph, because it gives you direct control over state transitions, tool interfaces and the browser layer.
Production agent architecture
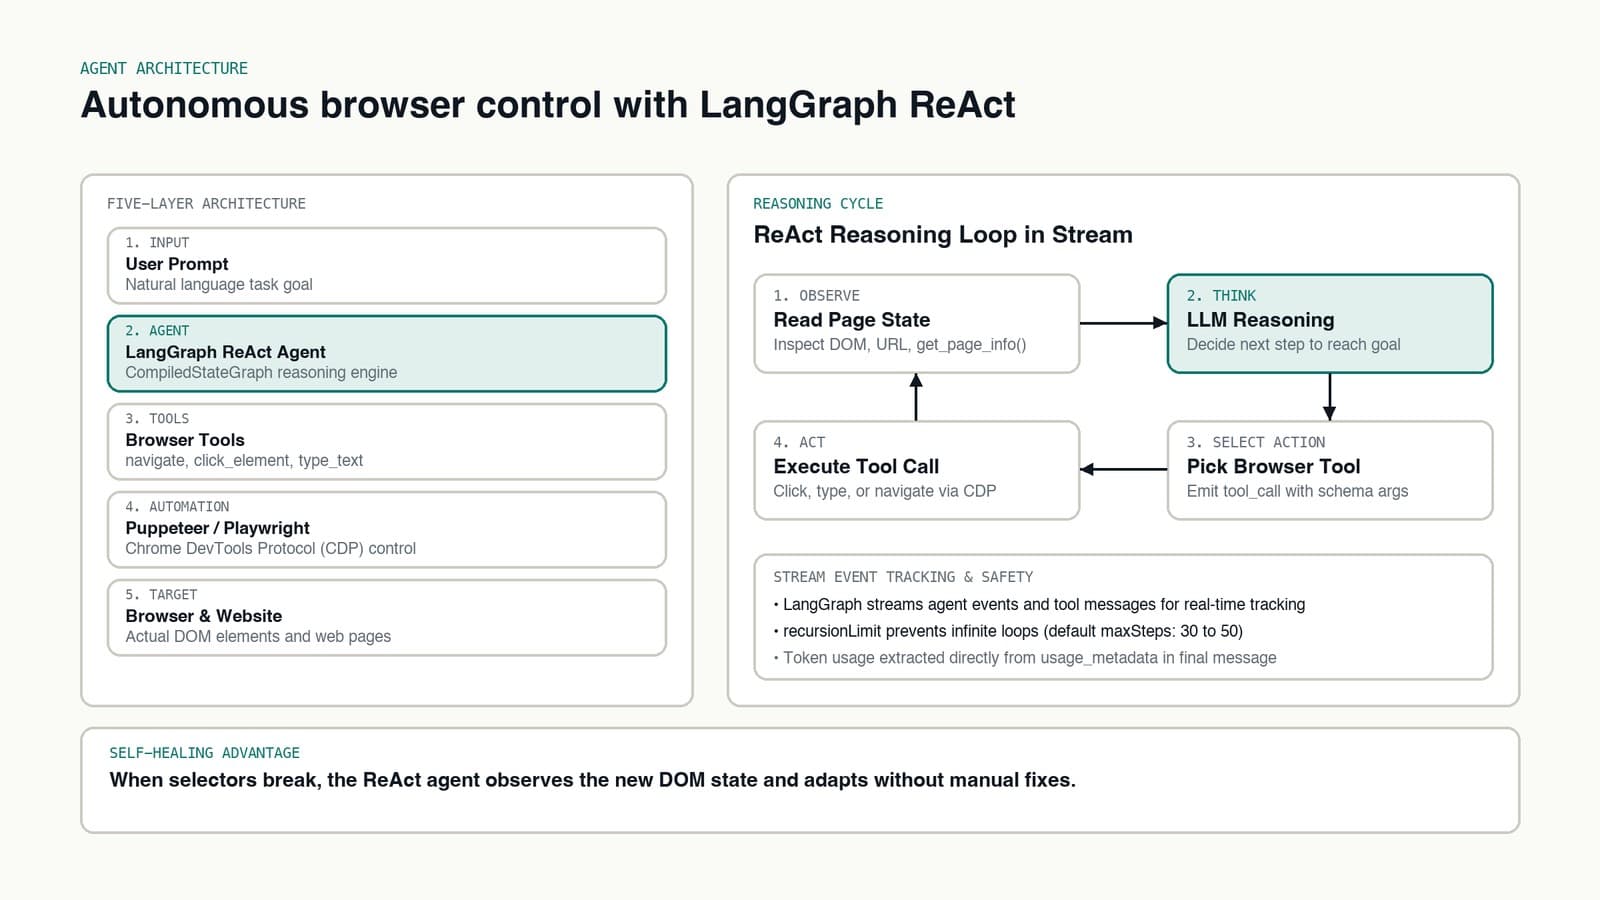
A resilient browser automation runtime has three layers:
- LangGraph state graph: runs the loop, manages message memory and enforces recursion limits.
- Browser engine: Puppeteer or Playwright in Chromium, driving the DOM over the Chrome DevTools Protocol (CDP).
- LLM reasoning model: reads the page state, plans tool calls and extracts structured data.
Core execution loop
The agent runs a ReAct (Reasoning and Acting) cycle:
- Observe: read the page and prune it.
- Think: the LLM checks what it sees against the goal.
- Select action: the model emits a structured tool call.
- Act: the browser driver runs it against the live page.
- Repeat: the state graph feeds the result back to the model until the task ends.
Brittle scripts vs resilient agents
Traditional automation ties itself to fragile CSS selectors:
// Hardcoded script: breaks on any class rename
await page.goto('https://example.com')
await page.click('#search-input')
await page.type('#search-input', 'query')
await page.click('#search-button')
await page.waitForNavigation()
An agent hands the planning to the model:
// Agent execution: resolves targets dynamically
await agent.executeTask('Go to example.com, search for "query", and return results')
| Trait | Static scripts | Autonomous agents |
|---|---|---|
| UI class rotation | Breaks immediately | Adapts to altered class names |
| Error recovery | Requires manual conditional branches | Retries with alternative locators |
| Complex flows | Hundreds of lines of procedural glue | Concise task prompt and tools |
| Debugging | Stack trace on failed selector | Trace log of model reasoning and tool calls |
| Maintenance burden | High on dynamic sites | Low across minor UI iterations |
Runtime requirements
You'll need:
- Node.js 18+, for native fetch and ES modules.
- TypeScript, for type safety across tool parameters and LangGraph state.
- LLM API access: OpenAI, Anthropic or Google Gemini credentials.
- Chromium: a local install or a remote CDP endpoint.
Core dependencies
Install LangChain, LangGraph and the validation library:
npm install @langchain/core @langchain/langgraph
npm install puppeteer-core zod
Then the provider package for your model:
npm install @langchain/openai
npm install @langchain/anthropic
npm install @langchain/google-genai
If you prefer Playwright over Puppeteer:
npm install playwright
npx playwright install chromium
Primitive browser tools
The agent touches the page only through small tools, each wrapped in a LangChain DynamicStructuredTool. Every tool has a Zod schema, so the model has to produce valid parameters.
import { DynamicStructuredTool } from '@langchain/core/tools'
import { z } from 'zod'
import type { Page } from 'puppeteer-core'

export const createBrowserTools = (page: Page) => {
  return [
    new DynamicStructuredTool({
      name: 'navigate',
      description: 'Navigate to a specific URL in the active tab.',
      schema: z.object({
        url: z.string().url().describe('Target absolute URL'),
      }),
      func: async ({ url }) => {
        await page.goto(url, { waitUntil: 'domcontentloaded', timeout: 30000 })
        return `Navigated to ${url}`
      },
    }),

    new DynamicStructuredTool({
      name: 'click_element',
      description: 'Click a DOM element matching a CSS selector.',
      schema: z.object({
        selector: z.string().describe('CSS selector of the target element'),
      }),
      func: async ({ selector }) => {
        await page.waitForSelector(selector, { visible: true, timeout: 10000 })
        await page.click(selector)
        return `Clicked element: ${selector}`
      },
    }),

    new DynamicStructuredTool({
      name: 'type_text',
      description: 'Type text into an input field matching a CSS selector.',
      schema: z.object({
        selector: z.string().describe('CSS selector of the input field'),
        text: z.string().describe('Text to enter'),
        clearFirst: z.boolean().default(true).describe('Clear existing value before typing'),
      }),
      func: async ({ selector, text, clearFirst }) => {
        await page.waitForSelector(selector, { visible: true, timeout: 10000 })
        if (clearFirst) {
          await page.click(selector, { clickCount: 3 })
          await page.keyboard.press('Backspace')
        }
        await page.type(selector, text)
        return `Typed into ${selector}`
      },
    }),
  ]
}
Tool design rules
- One action per tool. Let the agent plan sequences, instead of hiding logic in multi-action tools.
- Strict schemas. Use real types in Zod. Don't accept a loose string where you expect a number or a boolean.
- Useful return values. Return a confirmation or a detailed error, so the model can check what happened.
Prune the DOM before the model sees it
Raw HTML is a token furnace. A typical modern page has between 50KB and 500KB of markup, and most of it is SVG data, inline styles, script bundles and non-interactive container divs. Feed all that to a model and you waste context and invite hallucinations.
So prune it down to interactive elements and structural text. The script below drops hidden nodes, strips decorative markup and gives each actionable element a synthetic index ID (data-agent-id).
export async function getPrunedDomTree(page: Page): Promise<string> {
  return await page.evaluate(() => {
    const interactiveSelectors = [
      'button',
      'a[href]',
      'input',
      'select',
      'textarea',
      '[role="button"]',
      '[role="link"]',
      '[contenteditable="true"]',
    ].join(', ')

    const elements = Array.from(document.querySelectorAll(interactiveSelectors))

    const visibleElements = elements.filter((el) => {
      const rect = el.getBoundingClientRect()
      const style = window.getComputedStyle(el)
      return (
        rect.width > 0 &&
        rect.height > 0 &&
        style.visibility !== 'hidden' &&
        style.display !== 'none' &&
        style.opacity !== '0'
      )
    })

    return visibleElements
      .map((el, index) => {
        el.setAttribute('data-agent-id', String(index))
        const tag = el.tagName.toLowerCase()
        const text = (el.textContent || '').trim().replace(/\s+/g, ' ').slice(0, 60)
        const type = el.getAttribute('type') || ''
        const placeholder = el.getAttribute('placeholder') || ''
        const ariaLabel = el.getAttribute('aria-label') || ''
        const name = el.getAttribute('name') || ''

        const attributes = [
          `agent_id="${index}"`,
          type ? `type="${type}"` : '',
          name ? `name="${name}"` : '',
          placeholder ? `placeholder="${placeholder}"` : '',
          ariaLabel ? `aria-label="${ariaLabel}"` : '',
        ]
          .filter(Boolean)
          .join(' ')

        return `<${tag} ${attributes}>${text}</${tag}>`
      })
      .join('\n')
  })
}
Wrap this extractor in a tool:
new DynamicStructuredTool({
  name: 'get_pruned_dom',
  description: 'Returns visible interactive elements with synthetic agent IDs.',
  schema: z.object({}),
  func: async () => {
    const tree = await getPrunedDomTree(page)
    const url = page.url()
    const title = await page.title()
    return `URL: ${url}\nTitle: ${title}\nInteractive Elements:\n${tree}`
  },
})
This cuts observation payloads from 40,000 tokens to under 1,000 tokens per step. And the model points at elements by agent_id or visible attributes, instead of guessing long CSS selector paths.
Model provider configuration
Create the chat model with LangChain's provider wrappers:
import { ChatOpenAI } from '@langchain/openai'
import { ChatGoogleGenerativeAI } from '@langchain/google-genai'
import { ChatAnthropic } from '@langchain/anthropic'

// OpenAI GPT-4o-mini
const openAiModel = new ChatOpenAI({
  modelName: 'gpt-4o-mini',
  temperature: 0,
  openAIApiKey: process.env.OPENAI_API_KEY,
})

// Google Gemini Flash
const geminiModel = new ChatGoogleGenerativeAI({
  model: 'gemini-2.0-flash',
  temperature: 0,
  apiKey: process.env.GEMINI_API_KEY,
})

// Anthropic Claude 3.5 Sonnet
const anthropicModel = new ChatAnthropic({
  model: 'claude-3-5-sonnet-20241022',
  temperature: 0,
  anthropicApiKey: process.env.ANTHROPIC_API_KEY,
})
Temperature and determinism
Browser automation wants predictable output, so keep temperature low:
- 0.0: best for selector resolution, structured extraction and step execution.
- 0.2: fine for varying search queries or exploratory scraping.
- 0.5+: avoid in automation. High temperature brings hallucinated tool names and malformed parameters.
LangGraph agent orchestration
Build the agent graph with createReactAgent. LangGraph compiles the loop into a state graph with checkpointing, streaming and recursion limits.
import type { BaseChatModel } from '@langchain/core/language_models/chat_models'
import { createReactAgent } from '@langchain/langgraph/prebuilt'
import type { CompiledStateGraph } from '@langchain/langgraph'
import type { Page } from 'puppeteer-core'

export interface AgentStep {
  step: number
  tool: string
  input: Record<string, unknown>
  output?: string
  timestamp: string
}

export interface TaskExecutionResult {
  success: boolean
  output?: string
  error?: string
  steps: AgentStep[]
  durationMs: number
}

export class BrowserAgent {
  private page: Page
  private agent: CompiledStateGraph<any, any>
  private maxSteps: number

  constructor(config: { page: Page; model: BaseChatModel; maxSteps?: number }) {
    this.page = config.page
    this.maxSteps = config.maxSteps || 30
    const tools = createBrowserTools(this.page)

    this.agent = createReactAgent({
      llm: config.model,
      tools,
    })
  }

  async executeTask(task: string): Promise<TaskExecutionResult> {
    const startTime = Date.now()
    const steps: AgentStep[] = []

    try {
      const stream = await this.agent.stream(
        { messages: [{ role: 'user', content: task }] },
        { recursionLimit: this.maxSteps }
      )

      let finalContent = ''

      for await (const event of stream) {
        if (event.agent?.messages) {
          for (const msg of event.agent.messages) {
            if (msg.tool_calls?.length) {
              for (const call of msg.tool_calls) {
                steps.push({
                  step: steps.length + 1,
                  tool: call.name,
                  input: call.args,
                  timestamp: new Date().toISOString(),
                })
              }
            }
          }
        }

        if (event.tools?.messages) {
          for (const msg of event.tools.messages) {
            if (steps.length > 0 && !steps[steps.length - 1].output) {
              steps[steps.length - 1].output = String(msg.content)
            }
          }
        }

        if (event.agent?.messages) {
          const lastMsg = event.agent.messages[event.agent.messages.length - 1]
          if (lastMsg?.content && typeof lastMsg.content === 'string') {
            finalContent = lastMsg.content
          }
        }
      }

      return {
        success: true,
        output: finalContent,
        steps,
        durationMs: Date.now() - startTime,
      }
    } catch (err: any) {
      return {
        success: false,
        error: err.message || 'Execution failed',
        steps,
        durationMs: Date.now() - startTime,
      }
    }
  }
}
Event streaming and execution tracking
LangGraph streams chunks from both agent nodes and tool nodes. Use those events to keep an audit trail, watch the intermediate steps, and kill runaway loops before they hit token ceilings.
recursionLimit is your safety net. If the agent gets stuck in a cycle, it stops the run instead of clicking forever.
Deterministic form filling vs probabilistic navigation
Here's the split that matters most in production: let the model explore, but make writes deterministic.
Probabilistic navigation for unstructured discovery
On an unfamiliar layout, hunting for deep links or reading search listings, you can't predict the clicks upfront. So the agent reasons step by step: look at the pruned tree, pick the next move, click, look again.
// Open-ended navigation: agent resolves links dynamically
const searchResult = await agent.executeTask(
  'Navigate to news.ycombinator.com, find the first article about databases, and click its comments link'
)
Each step costs an LLM round trip of 1 to 3 seconds. For exploration, that flexibility is worth it.
Deterministic form operations for reliable writes
Forms with a known shape (signups, billing addresses, support tickets) are a different story. Filling them one field at a time through an LLM loop invites trouble. An agent handling 8 fields individually takes 8 to 16 LLM iterations, and risks skipped fields, validation errors and high latency.
Use a deterministic batch tool instead. The LLM turns the instructions into a structured payload once, and the tool fills every input in Chromium in one go.
export const createBatchFormTool = (page: Page) =>
  new DynamicStructuredTool({
    name: 'fill_form_batch',
    description: 'Fills multiple input fields deterministically in a single operation.',
    schema: z.object({
      fields: z.array(
        z.object({
          selector: z.string().describe('Target input selector'),
          value: z.string().describe('Value to fill'),
        })
      ),
      submitSelector: z.string().optional().describe('Submit button selector'),
    }),
    func: async ({ fields, submitSelector }) => {
      for (const field of fields) {
        await page.waitForSelector(field.selector, { visible: true, timeout: 5000 })
        await page.click(field.selector, { clickCount: 3 })
        await page.keyboard.press('Backspace')
        await page.type(field.selector, field.value, { delay: 20 })
      }

      if (submitSelector) {
        await page.waitForSelector(submitSelector, { visible: true, timeout: 5000 })
        await page.click(submitSelector)
      }

      return `Successfully populated ${fields.length} fields`
    },
  })
A batch form tool turns those 8 to 16 iterations into one step, which cuts token costs and avoids validation timeouts.
Structured data extraction
For scraping, don't ask the LLM to copy raw text across chat turns. Extract it with structured code inside the browser context:
export const createScrapeTool = (page: Page) =>
  new DynamicStructuredTool({
    name: 'extract_table_data',
    description: 'Extracts tabular rows from a specified container selector.',
    schema: z.object({
      rowSelector: z.string().describe('CSS selector for table rows or item cards'),
    }),
    func: async ({ rowSelector }) => {
      const data = await page.evaluate((sel) => {
        const rows = Array.from(document.querySelectorAll(sel))
        return rows.slice(0, 10).map((r) => (r.textContent || '').trim().replace(/\s+/g, ' '))
      }, rowSelector)
      return JSON.stringify(data)
    },
  })
Handling dynamic SPAs
Single-page apps built with React, Next.js or Vue bring timing traps that break naive scripts:
- Soft navigation without full reloads: SPAs update view states using client-side routers (
history.pushState). Standard Puppeteer calls likepage.waitForNavigation()hang and timeout because no browser document load event fires. - Hydration latency: Server-side rendered pages mount interactive buttons into the DOM before client JavaScript hydrates event listeners. Clicking a button during hydration executes an inert click event, dropping the action silently.
- Virtual DOM node detachment: React frequently unmounts and remounts elements during re-renders. A selector handle resolved in step one throws a
Node is detached from documenterror when clicked in step two.
Add explicit stability checks for client-side rendering:
export async function waitForSpaReady(page: Page, timeoutMs = 8000): Promise<void> {
  await page.waitForFunction(
    () => {
      // Confirm document readiness
      if (document.readyState !== 'complete') return false

      // Check for common loading indicators or aria-busy containers
      const busyElements = document.querySelectorAll('[aria-busy="true"], .loading, .spinner')
      return busyElements.length === 0
    },
    { timeout: timeoutMs }
  )
}

export async function clickSpaElement(page: Page, selector: string): Promise<void> {
  await waitForSpaReady(page)

  // Re-query locator immediately before interaction to avoid detached references
  await page.waitForSelector(selector, { visible: true, timeout: 5000 })
  await page.evaluate((sel) => {
    const el = document.querySelector(sel) as HTMLElement | null
    if (!el) throw new Error(`Element not found: ${sel}`)
    el.scrollIntoView({ behavior: 'instant', block: 'center' })
  }, selector)

  // Dispatch synthetic click with small settle delay
  await page.click(selector)
  await new Promise((resolve) => setTimeout(resolve, 300))
}
Fallback strategies when selectors break
Production web apps restyle all the time, and CSS selectors break. Utility-first frameworks and CSS modules generate class names like .btn_a8x9 or .sc-bwzfXH that change between builds.
One selector is a single point of failure. Give the agent several tiers to fall back through.
Multi-tier selector resolution
When the agent needs an element, try four tiers in order:
- Semantic test attributes: Check for
data-testid,data-cy, or stableidattributes. - Accessible name anchors: Query by ARIA role and label (for example,
button[aria-label="Save"]). - Text content locators: Match visible text content using XPath or CSS text pseudoclasses.
- Pruned DOM re-identification: If programmatic selectors fail, invoke the LLM with the local pruned DOM subtree to locate the matching node.
export async function resilientClick(
  page: Page,
  targets: {
    primarySelector: string
    ariaLabel?: string
    buttonText?: string
  }
): Promise<string> {
  const candidates: string[] = [targets.primarySelector]

  if (targets.ariaLabel) {
    candidates.push(`[aria-label="${targets.ariaLabel}"]`)
  }

  if (targets.buttonText) {
    candidates.push(`//button[contains(normalize-space(), "${targets.buttonText}")]`)
  }

  for (const locator of candidates) {
    try {
      if (locator.startsWith('//')) {
        const [el] = await page.$x(locator)
        if (el) {
          await (el as any).click()
          return `Clicked via fallback xpath: ${locator}`
        }
      } else {
        await page.waitForSelector(locator, { visible: true, timeout: 2000 })
        await page.click(locator)
        return `Clicked via selector: ${locator}`
      }
    } catch {
      // Continue to subsequent locator candidate
    }
  }

  throw new Error(`Failed to resolve element across ${candidates.length} locator candidates`)
}
Self-healing selector cache
When the LLM fallback finds an element, save the locator it found in a local JSON map or a database cache. Next run, try the cached locator first, so you don't pay the fallback latency twice.
Advanced orchestration patterns
Reusable task templates
Turn common workflows into structured prompt factories:
export const taskTemplates = {
  portalLogin: (email: string, secret: string) => `
    Navigate to https://example.com/login.
    Locate email and password inputs.
    Fill credentials deterministically and click the sign-in button.
    Wait until dashboard loads.
  `,

  tableExport: (targetUrl: string, rowCount: number) => `
    Navigate to ${targetUrl}.
    Wait for data grid to populate.
    Extract the top ${rowCount} table rows and return as structured JSON.
  `,
}
Context injection for domain constraints
Agents behave better with explicit boundaries. Put the domain rules straight into the base prompt:
const promptContext = `
Operational constraints:
- Stay within domain: *.company-portal.internal
- Do not interact with elements containing text "Delete" or "Archive"
- If an alert modal appears, dismiss it by clicking "Acknowledge"
`

await agent.executeTask(`${promptContext}\n\nTask: Export weekly report`)
Action validation and guardrails
Check stream events and block unsafe actions before they reach the browser:
export function validateActionSafety(toolName: string, args: Record<string, unknown>): void {
  if (toolName === 'navigate') {
    const url = String(args.url || '')
    const parsed = new URL(url)
    const allowedHosts = ['example.com', 'internal.company.com']

    if (!allowedHosts.some((h) => parsed.hostname.endsWith(h))) {
      throw new Error(`Navigation blocked: ${url} outside allowed domains`)
    }
  }
}
Putting it together: posting through a rich-text editor
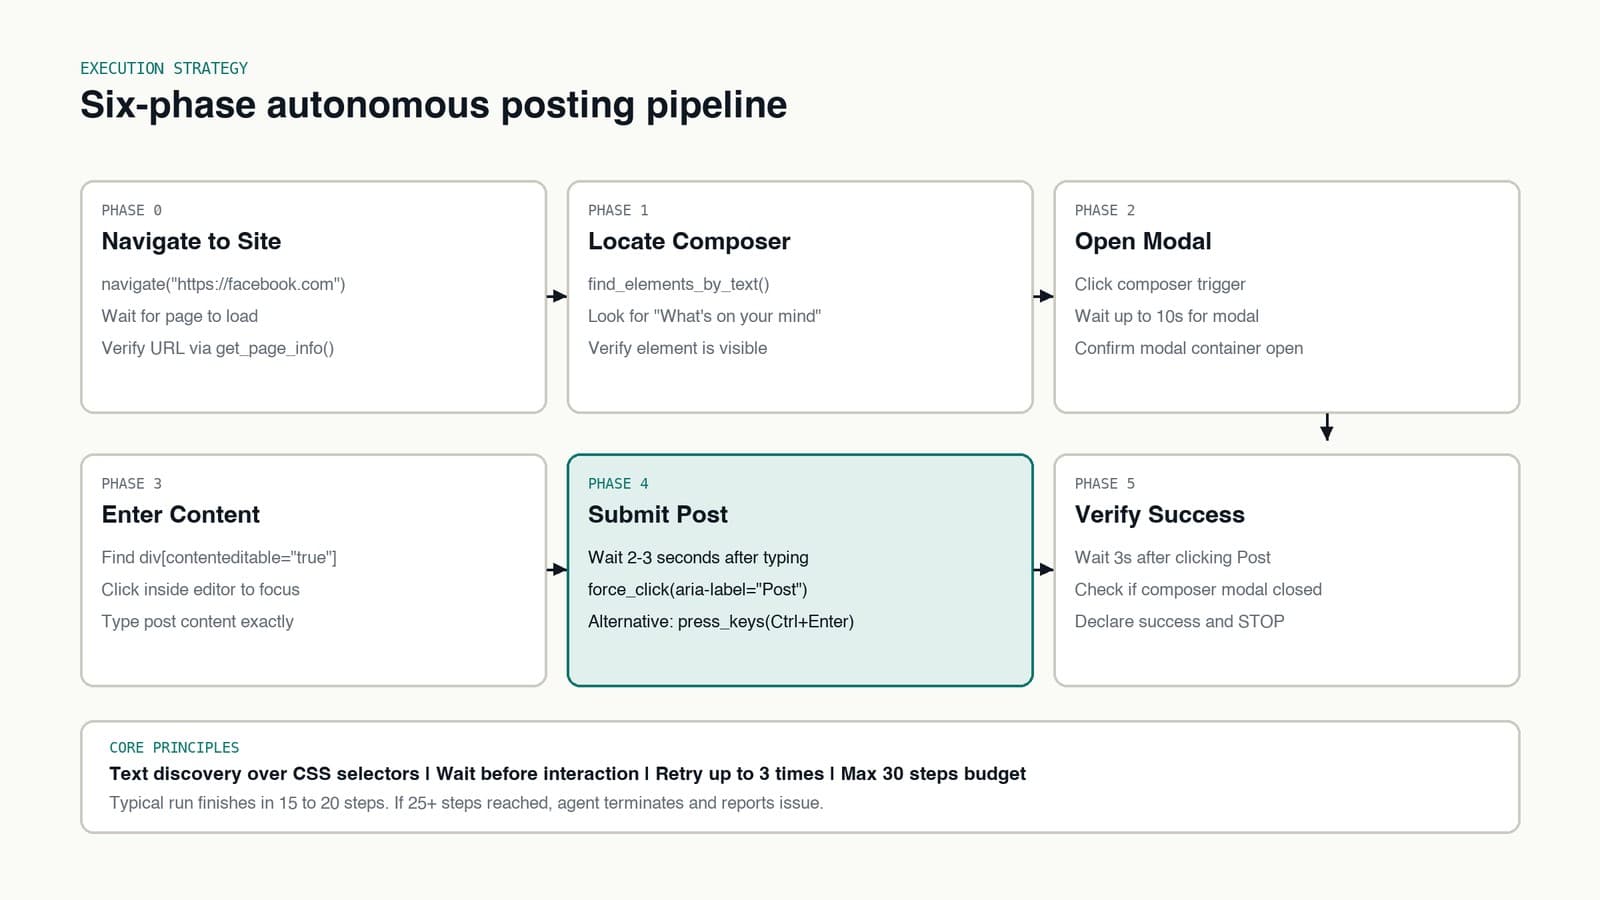
Nested modals and asynchronous rendering are where browser agents earn their keep, because selectors are unstable and hydration is slow.
Here's an agent script set up to navigate a rich-text posting interface:
import puppeteer from 'puppeteer-core'
import { ChatOpenAI } from '@langchain/openai'
import { BrowserAgent } from './BrowserAgent'

async function publishPortalUpdate(postContent: string) {
  const browser = await puppeteer.launch({
    headless: false,
    defaultViewport: { width: 1280, height: 800 },
  })
  const page = await browser.newPage()

  const model = new ChatOpenAI({
    modelName: 'gpt-4o-mini',
    temperature: 0,
    openAIApiKey: process.env.OPENAI_API_KEY,
  })

  const agent = new BrowserAgent({
    page,
    model,
    maxSteps: 25,
  })

  const task = `
Target: Open https://portal.internal/dashboard
Goal: Create a new team update with text: "${postContent}"

Execution guidelines:
1. Wait for dashboard view to settle.
2. Find the composer element matching "What is happening?" or input role.
3. Open the modal composer.
4. Type the update content into the editable body.
5. Locate the submit button and click it.
6. Verify the new post appears in the feed and terminate.
`

  const result = await agent.executeTask(task)
  console.log(`Execution status: ${result.success ? 'Success' : 'Failed'}`)
  console.log(`Total duration: ${result.durationMs}ms`)
  console.log(`Steps taken: ${result.steps.length}`)

  await browser.close()
  return result
}
Failure modes and debugging
Common runtime failures
- Recursion limit exceeded: the agent cycles between actions and never meets its completion criteria. Give it explicit termination conditions in the prompt.
- Stale DOM references: re-renders unmount elements while the model is thinking. Have tools query selectors at execution time instead of passing element handles between steps.
- Execution timeouts: third-party trackers or open WebSockets stop networkidle from ever resolving. Use domcontentloaded plus explicit selector readiness checks.
Debugging workflows
When something fails, capture what the page looked like and what the DOM held:
async function executeWithDiagnostics(agent: BrowserAgent, page: Page, task: string) {
  const result = await agent.executeTask(task)

  if (!result.success) {
    const timestamp = Date.now()
    await page.screenshot({ path: `error-state-${timestamp}.png` })
    const html = await page.content()
    console.error(`Execution failed. Diagnostics saved with ID: ${timestamp}`)
  }

  return result
}
Cost control and performance optimization
Token budget minimization
- Keep tool descriptions short. Every tool definition in the schema costs prompt tokens on every call.
- Prune observation markup. Never pass raw page HTML to the model.
- Use synthetic numeric IDs, not long CSS selector paths, in observation summaries.
Model selection by task complexity
| Task category | Recommended model | Input / Output cost (per 1M tokens) | Tradeoff |
|---|---|---|---|
| Standard navigation | GPT-4o-mini | $0.15 / $0.60 | Low latency, sufficient reasoning |
| High-volume scraping | Gemini 2.0 Flash | $0.075 / $0.30 | Lowest cost per step |
| Complex DOM reasoning | Claude 3.5 Sonnet | $3.00 / $15.00 | Highest accuracy on obscure layouts |
| On-premise runtime | Llama 3.3 70B | Infrastructure cost | Zero per-token API charges |
Execution bounds and circuit breakers
Set conservative step bounds in recursionLimit. Simple form work should finish within 8 to 12 steps. If a task goes past 20 steps, trip a circuit breaker, grab a screenshot and hand it to a human.
Automated testing strategies
Unit testing isolated tools
Check that each tool handles selector failures and bad parameters, with no LLM calls involved:
describe('click_element tool', () => {
  it('handles missing selector with clean error return', async () => {
    const mockPage: any = {
      waitForSelector: jest.fn().mockRejectedValue(new Error('Timeout 5000ms')),
    }
    const tools = createBrowserTools(mockPage)
    const clickTool = tools.find((t) => t.name === 'click_element')!

    await expect(clickTool.call({ selector: '#nonexistent' })).rejects.toThrow()
  })
})
Integration testing agent loops
Run integration tests against static HTML fixtures, so you can check the LangGraph state transitions without touching the network:
describe('BrowserAgent integration', () => {
  it('completes basic search workflow against mock fixture', async () => {
    const browser = await puppeteer.launch({ headless: true })
    const page = await browser.newPage()
    await page.setContent('<input id="search" /><button id="btn">Submit</button>')

    const agent = new BrowserAgent({ page, model: openAiModel })
    const result = await agent.executeTask('Type "test" into #search and click #btn')

    expect(result.success).toBe(true)
    await browser.close()
  })
})
End-to-end workflow verification
Run periodic health checks against canary environments, so you catch breaking changes before production does.
Troubleshooting runtime exceptions
Infinite loop prevention
Add explicit negative conditions to prompts:
Once the confirmation banner appears, do not click any further elements. Return the text and terminate.
Unresolved DOM nodes
If CSS selectors can't find an element, tell the agent to look by visible text or ARIA role instead of class hashes.
High latency mitigation
If runs are too slow, swap iterative multi-step tool calls for deterministic batch tools. Use lightweight models (such as GPT-4o-mini or Gemini 2.0 Flash) for routine steps.
Selection criteria for browser agents
Suitable workflows
- Vendor portals that keep changing, where selectors shift every sprint.
- Dynamic verification flows, where the next step depends on unpredictable UI feedback.
- Quick prototypes, to prove out a workflow before you write a custom API integration.
Workflows better suited for static scripts
- High-throughput bulk scraping. At 100,000 pages per hour, direct HTTP clients or static Playwright scripts are orders of magnitude faster and cheaper.
- Stable internal web apps with consistent
data-testidattributes that rarely change. - Sub-second latency needs. Agent reasoning adds 1 to 3 seconds per step.
Alternative frameworks
Browser Use
Browser Use provides an open-source browser agent engine with built-in stealth features and anti-captcha integrations. It is optimized for multi-tab browsing and stealth scraping.
Stagehand
Stagehand combines Playwright code with three AI primitives: act(), extract(), and observe(). It caches selector resolutions, providing self-healing automation without running a full ReAct loop on every action.
Skyvern
Skyvern executes complex web workflows using computer vision and multi-agent systems, designed for workflows that span diverse website layouts.
Runtime tradeoffs: Playwright vs Puppeteer
| Capability | Playwright | Puppeteer |
|---|---|---|
| Browser engine support | Chromium, Firefox, WebKit | Chromium focused |
| Auto-waiting mechanism | Native for clicks, inputs, and navigations | Manual waitForSelector required |
| Network inspection API | Built-in route routing and HAR capture | Request interception; no HAR |
| Language ecosystems | Node.js, Python, Java, .NET | Node.js native |
For a brand new agent, Playwright gives you better auto-waiting. Puppeteer is still a solid choice when you're embedding automation in an existing Node.js Chromium service.
Production setup economics
Typical monthly costs for a production deployment running about 2,000 agent jobs:
- LLM reasoning (GPT-4o-mini): ~$8/month
- Headless browser hosting (CDP grid or local containers): ~$15/month
- Total monthly cost: ~$23/month
Switch to Gemini Flash ($0.075 per 1M input tokens) with self-hosted Docker Chromium containers and it drops to under $10/month.
Takeaways
Browser agents take the maintenance grind out of brittle selector scripts. To make them dependable in production:
- Prune DOM representations to prevent context window bloat.
- Separate probabilistic navigation from deterministic form entry.
- Implement multi-tier selector fallbacks to handle CSS churn.
- Enforce strict recursion limits and streaming audit logs.
Small browser tools plus a structured state graph is what keeps an agent steady on pages that won't sit still.
Resources
Related posts
- Driving Multilogin browser profiles with Puppeteer and a LangGraph agent
Connect Puppeteer to Multilogin profiles over CDP and drive them with a LangGraph agent at about $0.02 a task on GPT-4o-mini, with fingerprint checks and clean teardown.
- Puppeteer in production: fallback selectors, real waits, clean exits
A Facebook class rename stopped 100+ accounts from posting. The fix: ARIA selectors, real waits, finally cleanup, a lock per account and screenshots on error.
- Four OpenTabs plugins for Facebook, Greenhouse, Toptal and Upwork
Four open-source OpenTabs plugins give a terminal agent 22 tools in my logged-in Chrome to triage friend requests, fill job forms and update freelance profiles.