- Published on
Scraping: back off, honour Retry-After, and never retry a 404
- Authors

- Name
- Nadim Tuhin
- @nadimtuhin
On this page
A scraper that gives up on the first failed request is brittle. One that retries everything is worse, because it keeps hammering a server that already asked it to slow down.
I wanted a retry helper that sits in the middle, so I wrote a small one and tested it against a server that fails on purpose. The rule it follows is short:
- Retry the failures that can clear on their own: 429 and 5xx, plus connection errors and timeouts.
- Don't retry the rest. A 404 will still be a 404 in a second.
- If the server says how long to wait, believe it.
The helper
import random, time, requests

RETRY = {429, 500, 502, 503, 504}

def get(url, tries=5, base=0.2, cap=5):
    for n in range(1, tries + 1):
        r = requests.get(url, timeout=(3, 10))
        if r.status_code not in RETRY:
            return r, n
        ra = r.headers.get("Retry-After")
        wait = float(ra) if ra and ra.isdigit() else min(cap, base * 2**n) * random.uniform(0.5, 1.0)
        print(f"  attempt {n}: {r.status_code}, waiting {wait:.2f}s")
        time.sleep(wait)
    r.raise_for_status()
Three details matter:
- Timeouts are a tuple.
(3, 10)is 3 seconds to connect and 10 to read. With no timeout,requestswaits forever. - Jitter. Multiplying by a random factor stops many workers from retrying in lockstep.
- A cap. Without
cap, the wait doubles into minutes.
What it did
I pointed it at a local server that returns 429 with Retry-After: 1 on the first call, 503 on the second, and 200 on the third. A second URL always returns 404:
  attempt 1: 429, waiting 1.00s
  attempt 2: 503, waiting 0.73s
flaky -> 200 {'ok': True, 'attempt': 3} after 3 attempts in 1.74 s
missing -> 404 after 1 attempt in 0.0 s
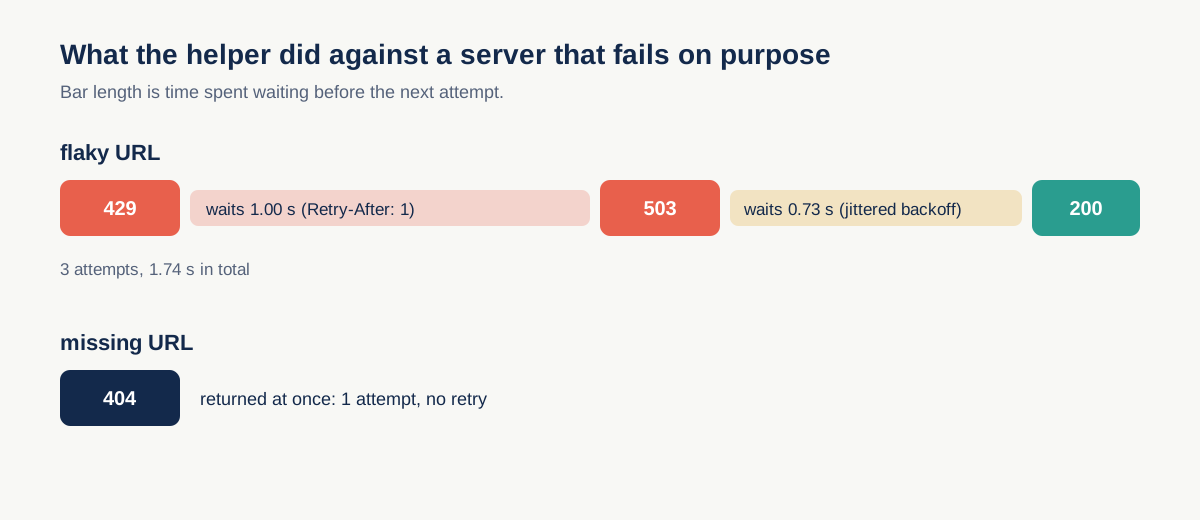
The 429 wait was exactly the 1 second the server asked for. The 503 had no header, so it fell back to the jittered backoff. The 404 came back at once, with no retries.
Limits of this sketch
- It doesn't parse a
Retry-Afterthat's an HTTP date, only seconds. - It retries
GETonly. Don't retry aPOSTunless the endpoint is idempotent. - Retries do nothing about your request rate. If you get a 429 often, send fewer requests.
Takeaways
- Sort failures into "might clear" and "won't clear" before you write any retry loop.
- Let
Retry-Afterbeat your own backoff when the server sends it. - Always set a timeout, add jitter, and cap the wait.
Frequently asked questions
- Which HTTP status codes should a scraper retry?
- Retry 429 and 5xx responses such as 500, 502, 503 and 504, plus connection errors and timeouts. Do not retry a 404, because it will still be a 404 a second later.
- How should a scraper handle the Retry-After header?
- Believe it. If the server sends Retry-After, wait that many seconds instead of using your own backoff. In my test the 429 wait was exactly the 1 second the server asked for, and a 503 without the header fell back to jittered exponential backoff.
- Why add jitter and a cap to retry backoff?
- Jitter stops many workers from retrying in lockstep, and a cap stops the doubling wait from growing into minutes. Also set a connect and read timeout, because requests waits forever with none.
Related posts
- Scraping: fail loudly when the page layout changes
A scraper that parses nothing and exits 0 looks healthy while it fills your database with gaps. A count check and a saved fixture catch it.
- Scraping: look for the page's JSON before you write a CSS selector
Many pages ship their data as JSON inside the HTML. Reading that survives a redesign that breaks every class-name selector.
- How I track my money with Hermes: the flow, not the numbers
Bank SMS and email alerts flow through one parser, a dedupe hash and a Google Sheet. A morning cron job drafts the summary. Only the flow, no figures.